AI Governance 101
Intelligent Agents — Module 2
A.Y. 2026/2027
Giovanni Ciatto
Compiled on: 2026-10-22 — printable version
Outline
- What is AI governance, and why should engineers care?
- Where should the model run? (cloud vs. on-premise)
- Regulation: GDPR, EU AI Act, national law, UniBo policy
- Open models, licensing, and “sovereignty”
- Which technique? Prompting vs. RAG vs. fine-tuning vs. agents
- Which model? Selection, documentation, and evaluation
- Responsibility remains human: enveloping and biases in AI use
- Exercises
What is AI governance?
- AI governance = the set of decisions, policies, and controls determining
- which AI systems (models, providers, techniques) an organization uses,
- how and where they are deployed,
- who is accountable for their outputs, and
- how they are monitored over time
- It is not (only) a legal matter: most governance decisions are engineering decisions, taken (often implicitly) while designing the system
- e.g. choosing a provider, a model, a deployment option, or whether a human reviews the outputs
- Making these decisions explicit, motivated, and documented is what distinguishes governance from improvisation
The five dimensions of the trade-off
Every choice about an AI-powered system implies a trade-off among:
- Quality: how good (accurate, reliable, consistent) are the outputs for the task at hand?
- Cost: how much do development, operation (per request, per month), and maintenance cost?
- Control: how much can we inspect, customize, reproduce, and keep running the system, regardless of third parties?
- Compliance: does the system respect laws (e.g. GDPR, AI Act), contracts, and internal policies?
- Time-to-market: how quickly can we ship (and change) the system?
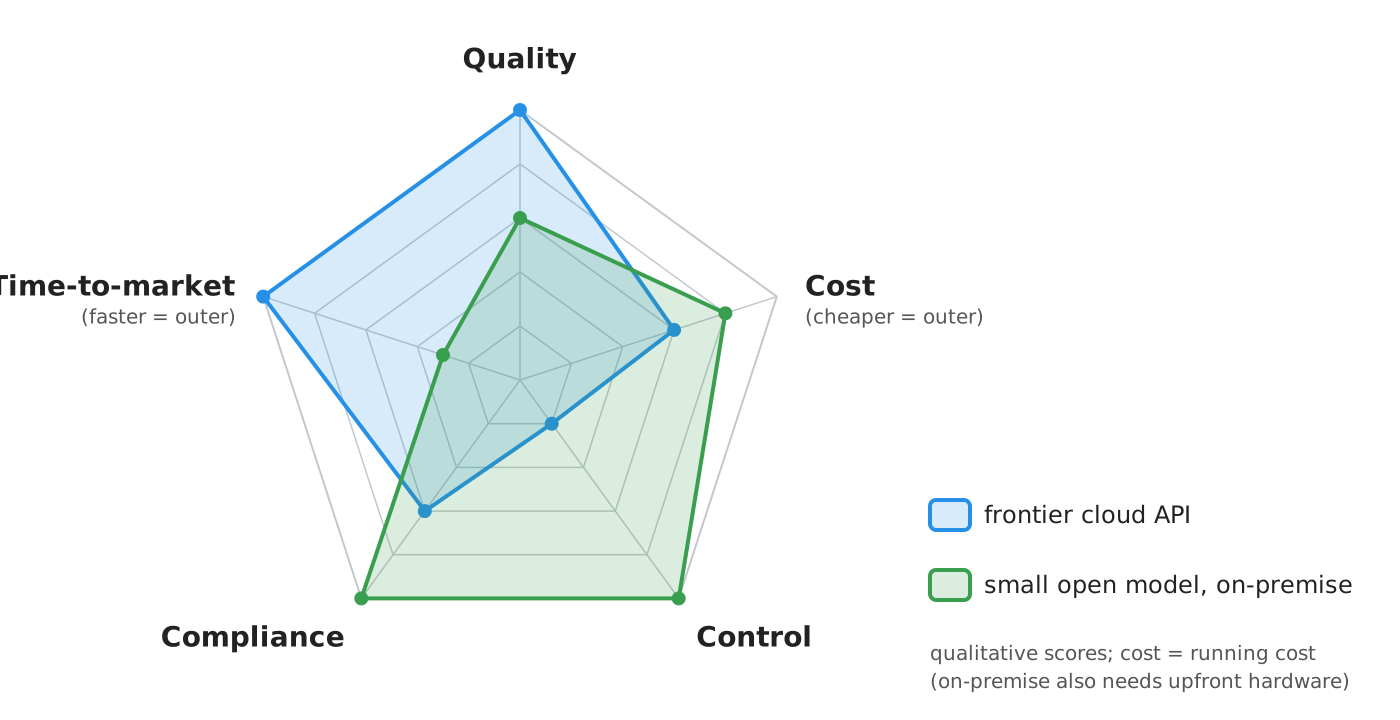
There is no option dominating all the others: governance is about choosing the right compromise for the use case at hand, and writing down why
Running example: a governance perspective
Recall the running example (PhD admission committee assistant):
- Data: passports, transcripts, and presentation letters of the candidates
- these are personal data (even identity documents!)
- Task: extract information, summarize, and score candidates
- outputs contribute to decisions affecting people’s access to education
- Stakeholders: candidates, committee members, the university (as the responsible organization), the AI provider(s)
Governance questions (to be answered throughout this lecture)
- Can we send these documents to a cloud provider? Under which conditions?
- Is this system subject to specific regulations? Which obligations follow?
- Should the committee blindly trust the scores? Who is accountable for them?
- Which model, technique, and deployment option are appropriate? How do we justify the choice?
Where should the model run? The general concept
Three main deployment options, differing in who runs the model, and where data goes:
- Proprietary cloud API: the model is owned and run by its provider (e.g. OpenAI, Anthropic, Google)
- you only get an API; data is processed on the provider’s infrastructure
- Open model, hosted by a third party: an open-weights model run by a cloud provider or aggregator (e.g. via Open Router, Hugging Face Inference Endpoints, cloud GPU rental)
- same model could be moved elsewhere; data still leaves your premises
- On-premise (a.k.a. self-hosted, local): an open-weights model run on your own hardware (e.g. via Ollama, vLLM)
- data never leaves your premises; you are responsible for hardware, operation, and updates
(cf. on-premise vs. on-cloud in the LLM-as-a-Service lecture)
Where should the model run? An intuitive example
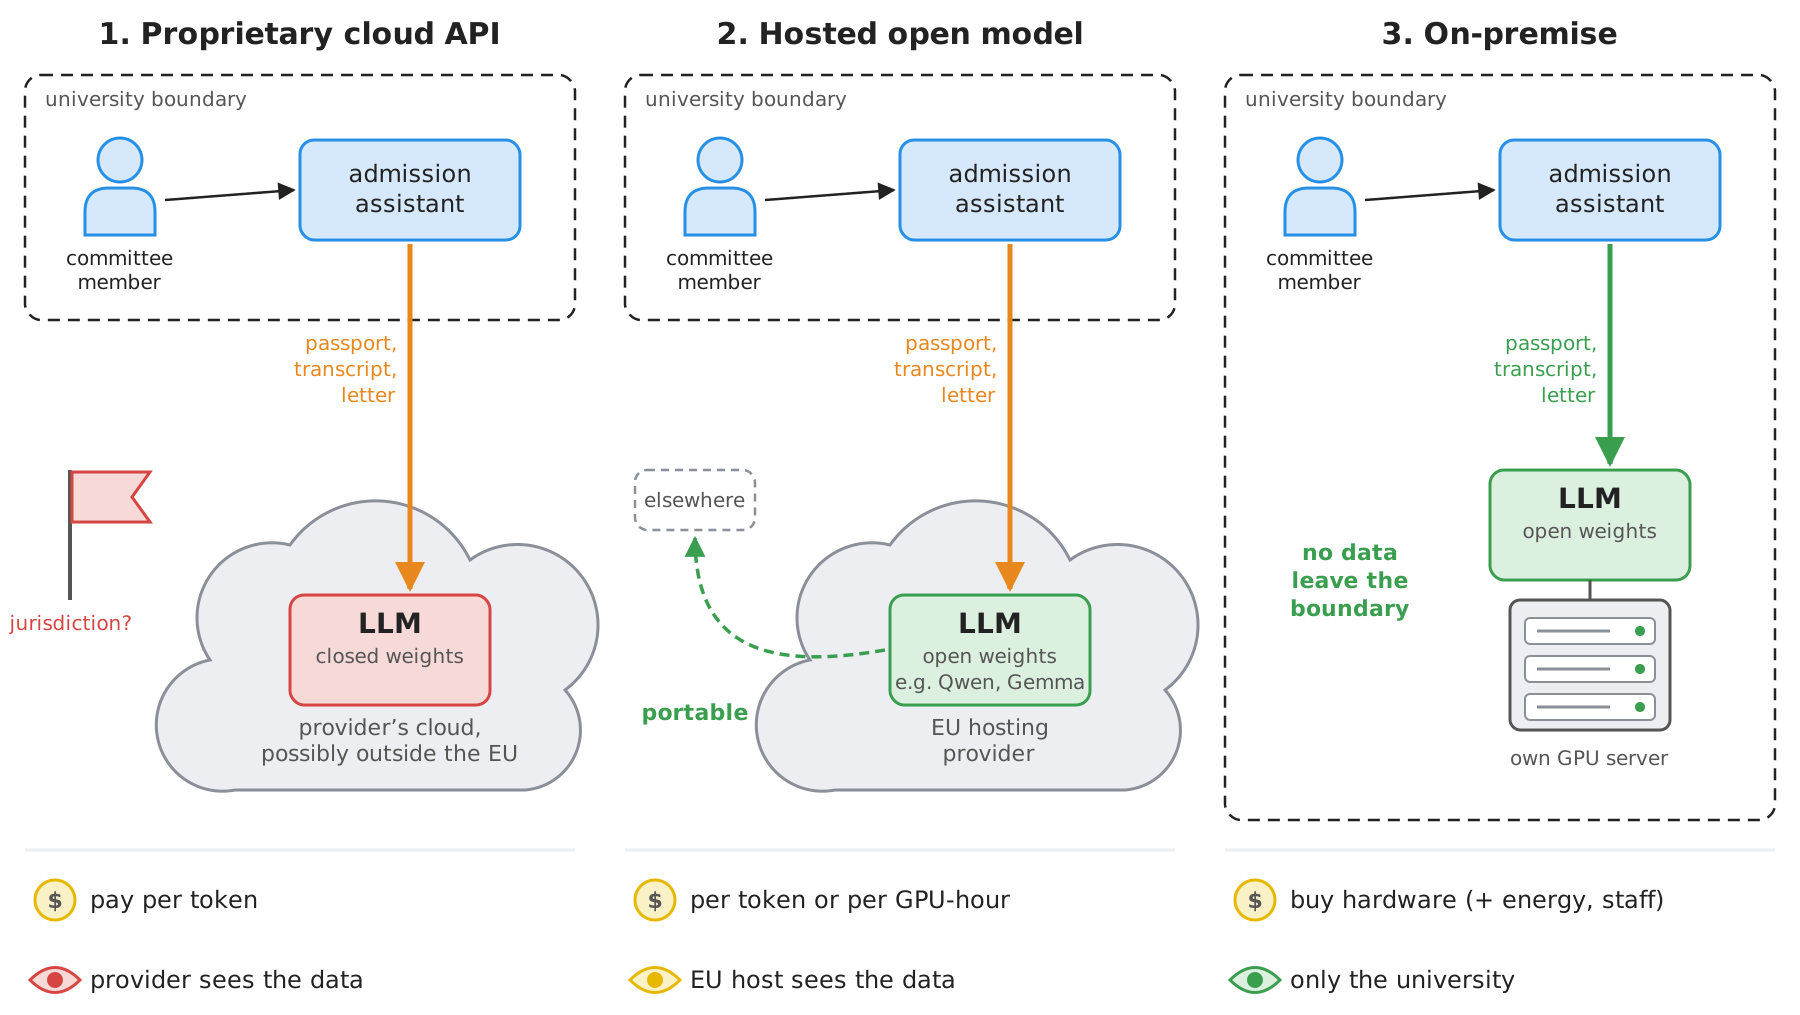
Deployment options: comparison
| Proprietary cloud API | Hosted open model | On-premise | |
|---|---|---|---|
| Quality | highest (frontier models) | good (best open models lag the frontier) | limited by the hardware (smaller models) |
| Cost structure | pay per token, no fixed costs | pay per token or per GPU-hour | hardware purchase + energy + staff; ~zero marginal cost |
| Scalability | virtually unlimited (within rate limits) | high | bounded by owned hardware |
| Control | low: models may change or be retired; no access to weights | medium: model is portable, provider is replaceable | full: versions pinned, runs offline |
| Privacy | data processed by provider (contracts, retention, jurisdiction matter) | same concerns, possibly with an EU provider | data stays in-house |
| Lock-in | high (proprietary features, prices) | low | low (but lock-in on hardware skills) |
| Time-to-market | minutes | hours | days to weeks (procurement, setup) |
| Footprint | energy per token hidden in the price | as for cloud APIs | power use measurable (and billed to you) |
- Energy matters: e.g. generative tasks cost orders of magnitude more energy than task-specific models (Luccioni et al., 2024); GPAI providers must document energy consumption (AI Act Art. 53, Annex XI)
- Hybrid solutions are common: e.g. on-premise for sensitive data, cloud for the rest; or a gateway routing requests according to data sensitivity
Deployment options: a worked cost example
Let’s estimate the yearly cost of the running example, under explicit (and rough) assumptions:
- 500 applications per year; each one = passport picture + transcript + letter ≈ 6k input tokens, plus ~1k tokens of prompts
- 5 requests per application (extraction, validation, scoring, …) $\implies$ ~35k input + ~5k output tokens per application
- hence, per year: 17.5M input + 2.5M output tokens
| Option | Price (USD per 1M input / output tokens) | Yearly cost |
|---|---|---|
| frontier proprietary model (e.g. Claude Opus 5.5) | \$4 / \$20 | 17.5 × 4 + 2.5 × 20 ≈ \$120 |
| small proprietary model (e.g. Claude Haiku 4.5) | \$1 / \$5 | ≈ \$30 |
| hosted open model, in the EU (e.g. Mistral Small 4, multimodal, Apache 2.0, on Mistral’s La Plateforme) | \$0.15 / \$0.60 | 17.5 × 0.15 + 2.5 × 0.6 ≈ \$4 |
| rented GPU, on demand (e.g. 24 GB GPU on RunPod) | ~\$0.35–0.75 per hour | a few hours per year ≈ \$5 (+ setup effort) |
| on-premise (a 24 GB GPU workstation) | ~€2–2.5k for the GPU alone | €2.5k+ upfront, + energy, + maintenance |
(prices as of September 2026: they change every few months, always re-check them)
At this scale, cost is not the deciding factor: compliance and control are. Things change at scale: e.g. one 80 GB GPU rented 24/7 costs ~\$2k/month, which buys ~100M output tokens of a frontier model per month. The break-even depends on volume, utilization, and model size
Regulatory framework
Regulation: the general picture
AI-powered software is subject to (at least) four layers of rules, each with a different object:
- the GDPR (Reg. (EU) 2016/679) regulates the processing of personal data, whatever the technology
- the EU AI Act (Reg. (EU) 2024/1689) regulates AI systems (by risk of their use) and general-purpose AI models
- national laws, e.g. the Italian AI law (Legge 132/2025)
- institutional policies, e.g. the UniBo GenAI policy
plus contracts (e.g. providers’ terms of service, data processing agreements) and licenses (of models, and of data)
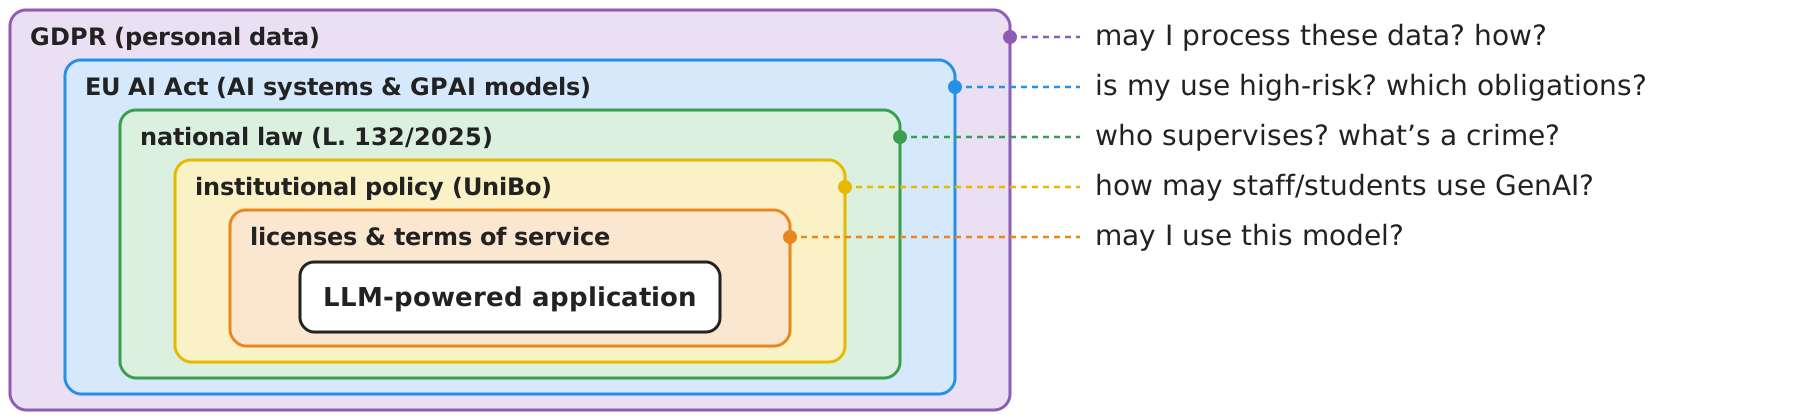
Disclaimer: this is an engineer’s overview, not legal advice: in real projects, involve your organization’s legal office and Data Protection Officer (DPO)
GDPR for LLM-powered applications: key concepts
- Personal data = any information about an identified or identifiable person (e.g. names, passports, grades, letters about someone)
- Controller (who decides why and how data is processed: e.g. the University) vs. processor (who processes data on behalf of the controller: e.g. the LLM provider)
- a Data Processing Agreement (DPA, Art. 28) with the provider is mandatory
- Principles (Art. 5): lawfulness, purpose limitation, data minimisation (send the LLM only what it needs!), accuracy, storage limitation, security
- privacy by design and by default (Art. 25): e.g. strip or pseudonymize personal data before sending prompts
- storage limitation vs. logging: logs kept ≥ 6 months (AI Act Art. 26(6)) contain personal data, so GDPR still applies: define a retention period (e.g. the appeal window + 6 months), then delete or pseudonymise
- International transfers (Chapter V): data leaving the EU need an adequacy decision (e.g. the EU–US Data Privacy Framework, upheld by the General Court in 2025, appeal pending) or other safeguards (e.g. standard contractual clauses)
- Data Protection Impact Assessment (DPIA, Art. 35): required for high-risk processing, e.g. new technologies used to evaluate or score people
- Automated decisions (Art. 22): people have the right not to be subject to decisions based solely on automated processing, with legal or similarly significant effects
- e.g. an admission rejection decided by an LLM alone
- About the models themselves: EDPB Opinion 28/2024 states that a model trained on personal data is anonymous only if extracting those data is very unlikely, and that an unlawfully developed model may taint its later use
GDPR in practice: providers and enforcement
What providers offer (as of September 2026)
| Provider | EU data residency | Zero data retention (ZDR) |
|---|---|---|
| OpenAI | yes (new projects, EU regional endpoints, surcharge) | for eligible customers, upon agreement |
| Anthropic | not on the first-party API; yes via cloud partners (AWS Bedrock, Google Vertex) | upon agreement |
| Google Vertex AI | yes (EU multi-region) | yes, disabling default caching |
| Microsoft Azure | yes (“Data Zone EU” deployments) | upon request (modified abuse monitoring) |
| Mistral | yes (EU or US regional inference) | upon request (default: 30 days retention for abuse monitoring) |
- Free tiers and consumer apps often allow providers to use your data for training: never send personal data there
The Italian Data Protection Authority (Garante) at work
- March 2023: ChatGPT temporarily blocked in Italy (lawful basis, transparency, age verification), then reopened under conditions
- December 2024: €15M fine to OpenAI, later annulled by the Court of Rome (March 2026) since the competent authority was the Irish one (one-stop-shop mechanism)
- January 2025: urgent limitation of processing for DeepSeek
EU AI Act: a risk-based approach
- Unacceptable risk $\rightarrow$ prohibited (Art. 5)
- e.g. social scoring, manipulative techniques, emotion recognition in workplaces and education, untargeted scraping of facial images
- High risk $\rightarrow$ strict obligations (Art. 6 and Annex III)
- e.g. CV screening, credit scoring, and education: systems to determine access or admission to educational institutions (Annex III, point 3(a)), to evaluate learning outcomes (3(b)), or to proctor exams (3(d))
- Transparency risk $\rightarrow$ disclosure obligations (Art. 50)
- e.g. chatbots must disclose they are AI; synthetic content must be marked; deepfakes must be labelled
- Minimal risk $\rightarrow$ no specific obligations
- e.g. spam filters, AI in video games
- Orthogonally: general-purpose AI (GPAI) models, with obligations for their providers (Art. 53; systemic risk: Art. 51, Art. 55)
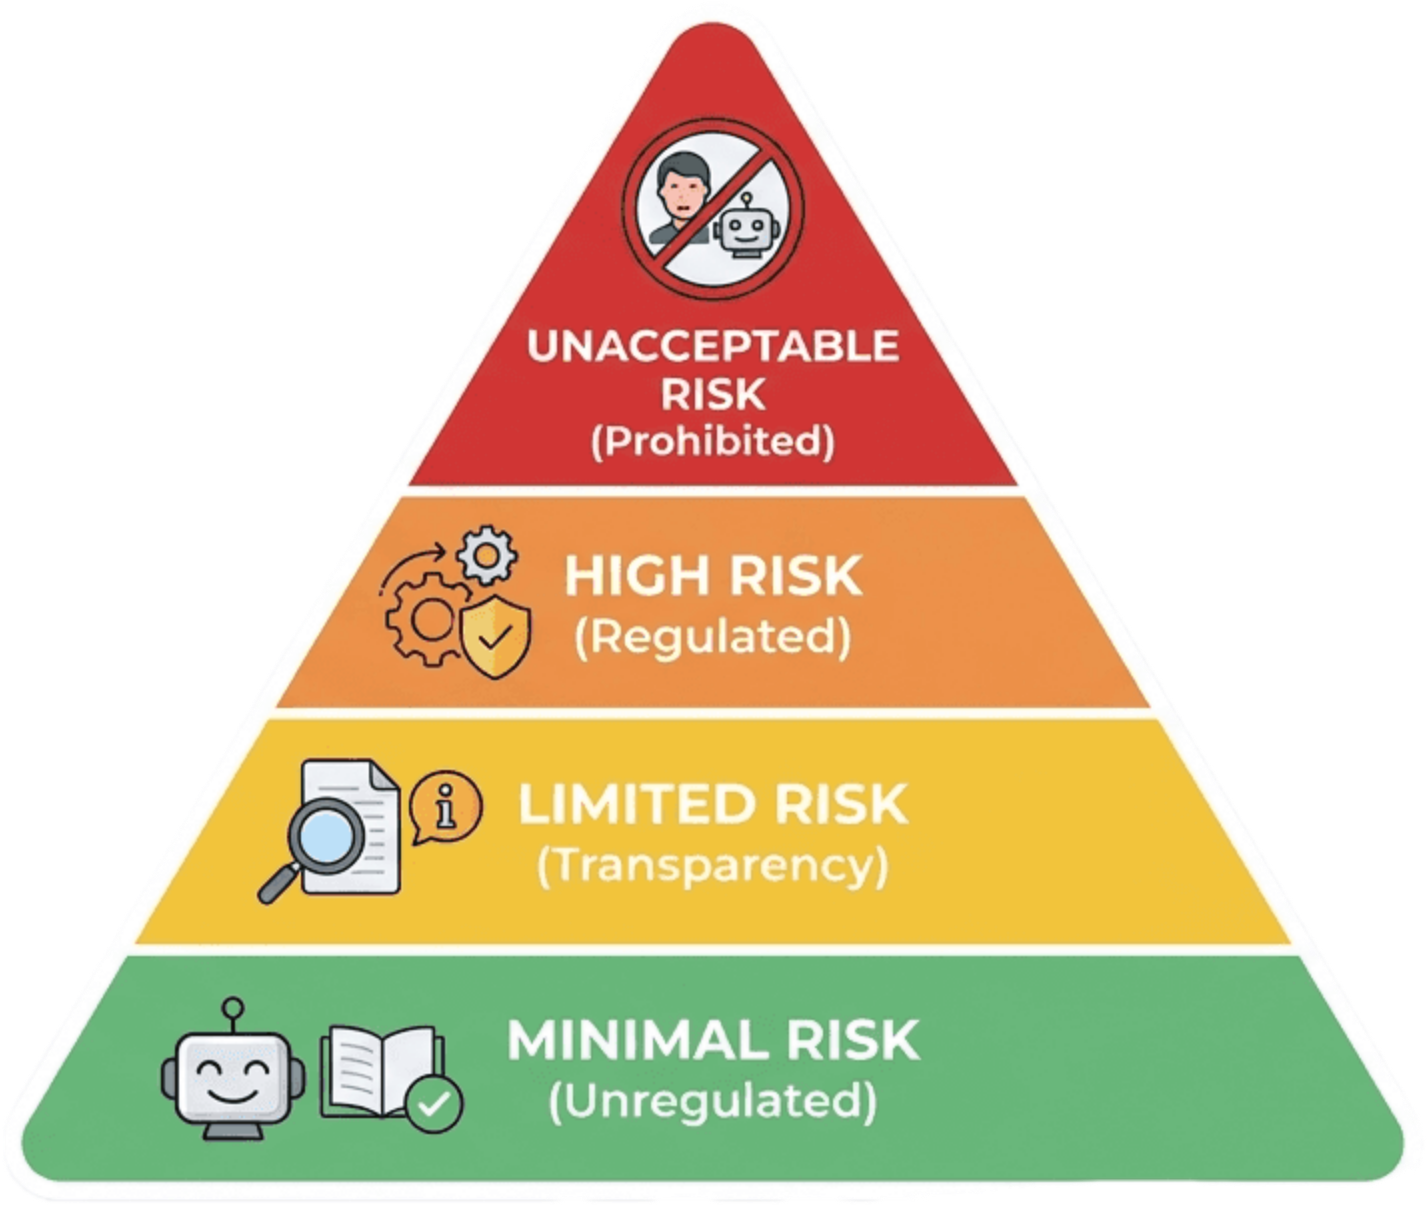
Our running example is high-risk: it contributes to deciding admission to a PhD programme. The same LLM, used to summarize news, would be minimal risk: the Act regulates the use, not the technology
EU AI Act: who must do what?
| Role | Who is it? | Main obligations (for high-risk systems) |
|---|---|---|
| Provider | who develops the system and puts it on the market / into service under its name | risk management (Art. 9), data governance (Art. 10), technical documentation (Art. 11), automatic logging (Art. 12), instructions for use (Art. 13), human oversight by design (Art. 14), accuracy & robustness (Art. 15), quality management, conformity assessment, registration, post-market monitoring |
| Deployer | who uses the system under its authority | use it as instructed; assign human oversight to competent, trained people; ensure input data are relevant; monitor it; keep logs for ≥ 6 months; inform affected people (Art. 26); public bodies: fundamental rights impact assessment (Art. 27) |
| Affected person | e.g. the candidate | right to an explanation of decisions based on high-risk AI output (Art. 86) |
- Beware: a deployer becomes a provider if it substantially modifies a system, or puts its own name on it (Art. 25)
- e.g. a University building its own admission assistant on top of an LLM API is the provider and the deployer of that system
- GPAI model providers (e.g. OpenAI, Mistral) must provide technical documentation to downstream providers, a copyright policy, and a public summary of training data (Art. 53); models with systemic risk (presumed above 1025 FLOPs of training, Art. 51(2)) also need evaluations, adversarial testing, incident reporting (Art. 55)
- open-source GPAI models are exempted from the documentation duties only, and only if they do not pose systemic risk (Art. 53(2), details later)
- a voluntary GPAI Code of Practice (July 2025) details how to comply
EU AI Act: timeline, literacy, penalties
Timeline (as amended by the Digital Omnibus on AI, Reg. (EU) 2026/1744)
| Date | What applies |
|---|---|
| 1 Aug 2024 | entry into force |
| 2 Feb 2025 | prohibitions (Art. 5), AI literacy (Art. 4) |
| 2 Aug 2025 | GPAI model obligations, governance structures |
| 2 Aug 2026 | general application, including transparency (Art. 50) |
| 2 Dec 2026 | new prohibitions (Art. 5(1)(ba)–(bb)): AI generating non-consensual intimate imagery (“nudifiers”) or child sexual abuse material; end of the grace period for the Art. 50(2) marking duty, for generative systems already on the market before 2 Aug 2026 |
| 2 Dec 2027 | high-risk systems of Annex III (e.g. education), postponed from 2 Aug 2026 |
| 2 Aug 2028 | high-risk systems of Annex I (safety components of regulated products), postponed from 2 Aug 2027 |
EU AI Act: literacy, penalties, standards
- AI literacy (Art. 4): providers and deployers must take measures to support the AI literacy of their staff (this course is part of it!)
- as amended by the Omnibus: previously, they had to ensure a sufficient level of literacy
- Penalties (Art. 99): up to €35M or 7% of worldwide turnover for prohibited practices; up to €15M or 3% for most other violations
- Transparency: a Code of Practice on AI-generated content details marking and labelling
- Standards: conformity in practice goes through harmonised standards (CEN-CENELEC JTC 21, still being drafted: one reason for the Omnibus delay); AI management systems: ISO/IEC 42001:2023; outside the EU: NIST AI RMF 1.0 (2023), plus its GenAI profile (NIST AI 600-1, 2024)
National law and institutional policies
Italy: Legge 23 settembre 2025, n. 132 (in force since 10 Oct 2025)
- complements the AI Act: AgID and ACN are the national AI authorities (Art. 20)
- public administration: AI is only instrumental, the human official remains solely responsible for decisions (Art. 14)
- intellectual professions: AI only for supporting activities, and clients must be informed (Art. 13)
- minors: under 14s need parental consent to use AI (Art. 4)
- copyright: only human works are protected (AI-assisted ones are, if they result from the author’s intellectual effort); rules on text and data mining (Art. 25)
- new crime: unlawful dissemination of AI-generated deepfakes (Art. 26)
- health: AI supports, the physician decides (Art. 7); work: employers must inform workers about AI use (Art. 11)
- delegated decrees (Art. 24): approved in final reading on 4 Aug 2026; the one on police use and liability is D.Lgs. 160/2026 (GU 15 Sep 2026), the one on authorities, training, and work was expected in Oct 2026
University of Bologna: GenAI policy for teaching and research
- GenAI use is allowed: principles of human centrality, transparency, accountability, accuracy, respect for rights
- substantial uses (e.g. AI-written papers, theses, or assessed work) must be declared; GenAI cannot be an author
- no substantial use where it affects others: e.g. peer review, evaluating research projects, grading students
- no personal data of third parties, confidential or unpublished material in online GenAI tools, without a legal basis and guarantees
- a separate policy for administrative staff exists
For the running example: scores must remain suggestions to the committee, candidates’ data must not go to consumer chatbots, and the University is accountable for the whole process
Open models, licensing, and “sovereignty”
What makes a model “open”? The general concept
A model release is a bundle of separately openable artifacts: downloading one of them (usually the weights) says little about the others
| Component | What a useful release contains | What it enables |
|---|---|---|
| Weights | final parameters (ideally also intermediate checkpoints) | local inference, fine-tuning, independent hosting |
| Inference code | architecture, tokenizer, generation code, configuration | actually running the weights |
| Training code & recipe | data processing, hyper-parameters, training and post-training (SFT, RL) pipelines | understanding how the weights arose; re-training |
| Training data | the actual training mixture, in training-ready form | data auditing, contamination analysis, exact reproduction |
| Data information | provenance, sources, filtering and selection processes | a (weaker) substitute when data cannot be redistributed |
| Documentation | model card, technical report, evaluations, limitations | auditability, downstream risk assessment |
| Licenses | separate licenses for weights, code, and data | knowing what you may legally do with all the above |
Openness is graded, not binary
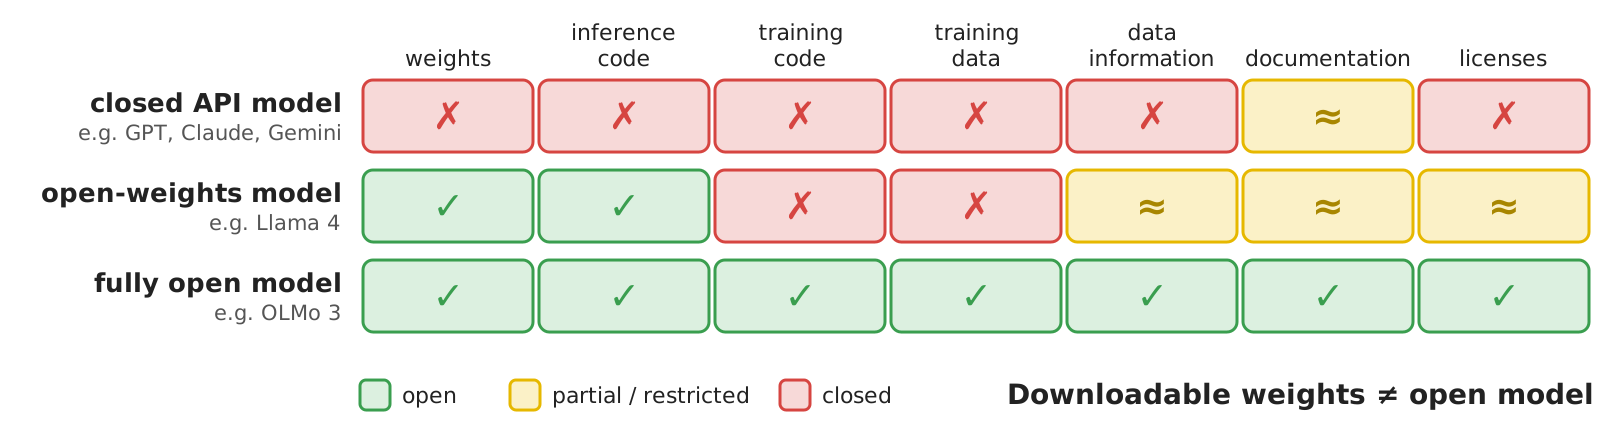
| Framework | Question it answers |
|---|---|
| Liesenfeld & Dingemanse, FAccT 2024 | how open is a release in practice? (14 dimensions, 40 text LLMs + 6 text-to-image models) |
| European Open Source AI Index | which open-science artifacts were actually released? (graded score; top ranks in July 2026: YuLan-Mini, BLOOMZ, OLMo 3, Apertus) |
| Stanford Foundation Model Transparency Index (Dec. 2025) | how transparent are providers? (mean score 41/100, down 17 from 2024; IBM 95, DeepSeek 32, Alibaba 26: open weights $\neq$ transparency) |
| OSI Open Source AI Definition | does a system meet a normative definition of “open source AI”? (next slide) |
- Open-washing: presenting a model as “open” or “open source” based on one disclosed component (typically the weights), while the artifacts or legal freedoms needed to study, reproduce, modify, or freely use it are missing
- e.g. Llama 4 (downloadable weights, restrictive license), Gemma 3 (custom terms with use restrictions), Mistral 3 (called “open-source” by its vendor: Apache 2.0 weights, undisclosed training data)
- by contrast, OpenAI calls gpt-oss “open-weight”: the more accurate term
The OSI Open Source AI Definition (OSAID 1.0, Oct. 2024)
- Users must be able, without asking permission, to:
- use the system for any purpose
- study how it works
- modify it for any purpose
- share it, with or without modifications
- This requires the preferred form for making modifications:
- data information: enough detail on training data for a skilled person to build a substantially equivalent system
- code: the complete training and inference pipeline
- parameters: weights and configuration, under open terms
- Controversy: OSAID does not require releasing the training data itself (cf. OSI’s FAQ)
- OSI: data may be personal, copyrighted, or confidential, so requiring it would exclude too many systems
- critics: without the data, exact reproduction and data-level auditing are impossible
- OSI’s initial validation found that Pythia, OLMo, Amber, CrystalCoder, and T5 passed, while Llama 2, Grok, Phi-2, and Mixtral did not
- a snapshot of 2024, not a certification registry for later versions
The licensing landscape (as of September 2026)
| Category | Examples | What is open | Main limitation |
|---|---|---|---|
| Closed (API-only) | GPT, Claude, Gemini, Mistral’s “Premier” models | API + documentation | no weights; usage governed by terms of service |
| Open weights, restrictive license | Llama 4, Gemma 3, Teuken v0.6, BLOOM (RAIL) | weights, inference code | use-based, geographic, commercial, or downstream restrictions: not “any purpose” |
| Open weights, permissive license | Gemma 4, Qwen3, DeepSeek-R1, gpt-oss, Mistral Large 3 / Small 4 | weights under Apache 2.0 or MIT | training data and full pipeline not released |
| Fully (or nearly) open | OLMo 3, Apertus, Minerva | weights + code + data (or data pipeline) + docs | reproduction still needs enormous compute |
The licensing landscape (as of September 2026)
Licenses change across versions: always check the exact checkpoint
| Model | Before | Now |
|---|---|---|
| Gemma | Gemma 3: custom Gemma Terms, with cascading use restrictions | Gemma 4 (2026): Apache 2.0 |
| DeepSeek-V3 | original V3: custom DeepSeek Model Agreement | V3-0324: relicensed under MIT (March 2025) |
| Mistral | historically mixed | still mixed: Large 3 and Small 4 Apache 2.0, Medium 3.5 “Modified MIT”, several models proprietary |
| Teuken | v0.4-commercial: Apache 2.0 | v0.6: non-commercial (“newer” does not mean “more permissive”) |
| iGenius → Domyn | Italia 9B: MIT; Italia 10B: custom, non-open license | rebranded Domyn (June 2025); Domyn Small 10B (May 2026): MIT |
What do restrictive licenses mean in practice?
| License | On-premise use | Fine-tuning | Hosted service | Redistribution |
|---|---|---|---|---|
| Llama 4 (license, AUP) | yes, except multimodal models for individuals/companies based in the EU | yes | yes (EU end users of products are carved out) | “Built with Llama” attribution; derived models named “Llama…”; separate license above 700M monthly active users |
| Gemma 3 (terms) | yes, within the prohibited-use policy | yes, derivatives inherit the restrictions | counts as distribution | restrictions must be passed to downstream users; Google may restrict use “remotely or otherwise” (a contractual right, not a kill switch) |
| OpenRAIL (OpenRAIL-M) | yes, for permitted purposes | yes, for permitted purposes | yes, users bound to use restrictions | use restrictions must be passed on |
| Apache 2.0 / MIT | yes | yes | yes | yes, with attribution/notices (and patent clauses, for Apache) |
Running example: the admission assistant must read passport pictures, hence needs a multimodal model. The University of Bologna is an EU organization: under Llama 4’s acceptable use policy, it is not granted the right to use Llama 4’s multimodal models. Gemma 4, Qwen3, or Mistral’s Apache models raise no such issue
Derivatives: fine-tunes, distillation, merges, data, outputs
- Fine-tunes remain subject to the base model’s license: easy for Apache/MIT, restrictions propagate for Gemma 3 and Llama
- Distillation is license-specific:
- Merges: a merge of models A and B must (conservatively) satisfy both licenses; a restrictive component is not “washed away”
- whether weights are copyrightable at all is still legally unsettled
- Training data has its own license: e.g. OLMo 3 is Apache 2.0, but its dataset Dolma 3 is ODC-By (attribution required), and its sources may carry further terms
- Outputs: “the vendor claims no rights on outputs” $\neq$ “outputs are free of restrictions”
- e.g. using Llama outputs to train a distributed model triggers Llama’s naming requirement
- proprietary vendors offer copyright indemnities for outputs (e.g. Microsoft’s Copilot Copyright Commitment, Google’s generative AI indemnification, OpenAI’s Copyright Shield, Anthropic’s commercial terms), usually for paid or enterprise tiers only, and with conditions; open-weights licenses give none
- in Italy, only human works are protected (L. 132/2025, Art. 25: cf. below)
Open models under the EU AI Act
| GPAI provider duty (Art. 53) | Ordinary GPAI | Free/open-source GPAI |
|---|---|---|
| (a) technical documentation (for the AI Office) | required | exempt |
| (b) information for downstream providers | required | exempt |
| (c) policy to comply with EU copyright law (incl. text-and-data-mining opt-outs) | required | still required |
| (d) public summary of training content (AI Office template) | required | still required |
| systemic-risk obligations (Art. 55) | if > 1025 FLOPs (presumption of Art. 51(2)) | no exemption |
- To qualify, the model must be released under a license allowing access, use, modification, and distribution, with weights, architecture, and usage information public
- this is much weaker than OSAID: no training data or training code needed
- Non-EU providers of open-source GPAI are also exempted from appointing an EU authorized representative (Art. 54(6)), unless the model poses systemic risk
- cf. the Commission’s AI Act Service Desk FAQ on open-source GPAI models
The AI Act gives open-source GPAI a documentation discount: not a copyright exemption, not a training-data-summary exemption, and not a systemic-risk exemption
“Sovereign AI”: a framing, and its limits
- Several European and Italian actors frame open, locally-developed models as a matter of digital sovereignty
- reduce dependency on US and Chinese providers; better support for EU languages; compliance with EU law
- The framing mixes (at least) three distinct goals, which should not be conflated:
- where a model is developed (nationality of the developer)
- where it is executed, and data are processed (operational control)
- whether its making can be inspected and reproduced (auditability)
- Goals 2 and 3 do not require goal 1:
- any open-weights model (e.g. Qwen3, gpt-oss, OLMo 3) can run in an EU data centre
- the most reproducible models are not necessarily European (e.g. OLMo 3, from the US), and a European vendor may disclose little (e.g. Mistral)
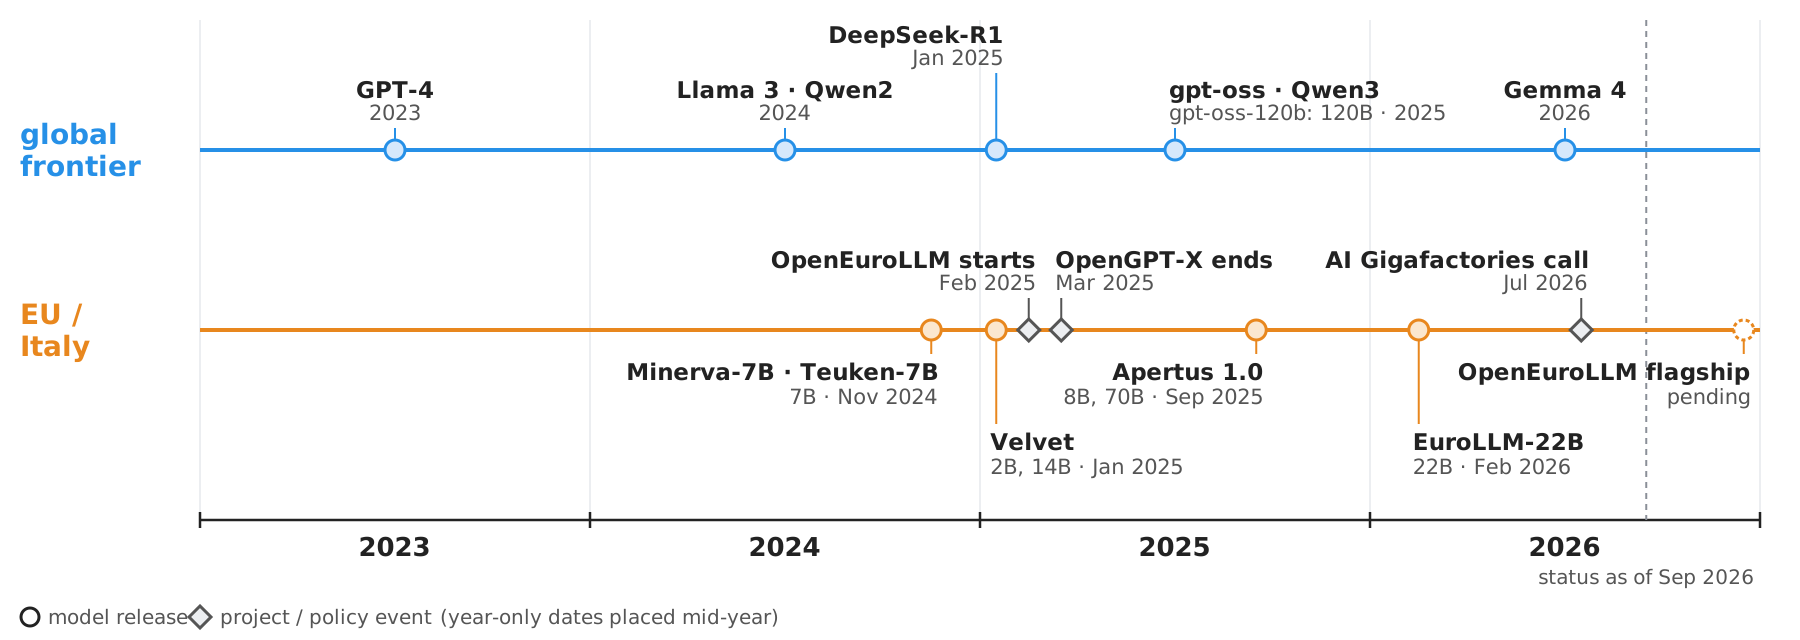
Skeptical reading: for an engineer, where the model runs and what its license allows matter much more than who trained it. The evidence (next slides) suggests that EU and Italian models are mostly small, late, and not competitive with the frontier, nor with the best global open-weights models
The gap, in numbers
Data from the Stanford AI Index 2026 (2025 figures):
| United States | China | Europe | Italy | |
|---|---|---|---|---|
| Notable AI models released (Epoch AI, Fig. 1.1.13) | 59 | 35 | 1 (France); 1 more in the UK | none listed |
| Private AI investment (Quid, Fig. 4.2.8, 4.2.11) | \$285.9B | \$12.4B | \$20.9B (France \$4.4B, Germany \$3.9B) | < \$1B (not in the top 15) |
| … of which generative AI (Fig. 4.2.10) | \$163.6B | \$1.5B | \$3.2B | — |
| Newly funded AI companies (Fig. 4.2.9) | 1,953 | 161 | e.g. Germany 92, France 84 | 38 |
| Growth of private AI investment, 2024 $\rightarrow$ 2025 (Fig. 4.2.11) | +160% | +32% | +7% | — |
- The gap is not closing: it is widening, at least for private investment
- Caveats: private investment understates state funding (notably China’s, and EU/national programmes such as EuroHPC AI Factories); counts by affiliation may double-count multinational teams
Italian initiatives
| Model | Who | What | License | Status (Sep. 2026) |
|---|---|---|---|---|
| Minerva | Sapienza NLP, within the FAIR PNRR project; trained on CINECA’s Leonardo | 350M, 1B, 3B, and 7B, from scratch; 1.14T Italian + 1.14T English + 200B code tokens | Apache 2.0, open data | 7B presented in Nov. 2024; still the flagship, research-grade |
| LLaMAntino / ANITA | Univ. of Bari | fine-tunes of Llama, Mistral, gpt-oss for Italian (not trained from scratch) | inherited; ANITA-NEXT’s metadata says Apache 2.0, its card says “research only” | active research project; license hygiene is weak |
| Velvet | Almawave (private); trained on Leonardo | 2B and 14B, 6 languages (~23% Italian for the 14B) | Apache 2.0 | released Jan.–Feb. 2025, static since |
| Italia → Domyn Small | iGenius (private), renamed Domyn in June 2025 | Italia 9B (2024), then 10B; Domyn Small 10B (May 2026), 50+ languages | Italia 9B: MIT; Italia 10B: custom, non-open; Domyn Small: MIT | company focus moved to proprietary large models |
- A “national” model says nothing about its openness: compare Minerva (Apache, open data) with Italia 10B (restrictive license)
- Italian models trained from scratch range from 0.35B (Minerva) to 14B (Velvet); larger ones (e.g. ANITA-NEXT 24B) are fine-tunes of foreign models: one or two orders of magnitude below the frontier
European initiatives
| Initiative | Who | What | License | Status (Sep. 2026) |
|---|---|---|---|---|
| EuroLLM | IST Lisbon, Univ. of Edinburgh, Unbabel, et al.; EuroHPC and Horizon Europe funding | 1.7B, 9B, 22B; 35 languages (all 24 EU ones), ~4T tokens | Apache 2.0 | 22B released Feb. 2026 |
| OpenEuroLLM | 20 members, led by Charles University and AMD Silo AI; Digital Europe grant (Feb. 2025, 3 years) | “truly open” models for all EU languages | open (planned) | so far only small reference models (e.g. 38 monolingual 2.15B, with HPLT); flagship still pending |
| OpenLLM-France | French consortium, Bpifrance funding | Lucie-7B, then Luciole 1B/8B/23B (~30% French) | open data, weights, code | research project |
| Teuken / OpenGPT-X | Fraunhofer, FZ Jülich, et al.; ~€14M from the German government | 7B, 24 EU languages | v0.4: Apache 2.0; v0.6: non-commercial | project ended in March 2025; models still downloadable |
| Apertus | ETH Zurich, EPFL, CSCS (Swiss AI Initiative: CHF 20M + 10M GPU-hours) | 8B, 70B; 1.5 (July 2026) adds images, reasoning, tools | Apache 2.0, fully open | the most complete open release in Europe; 2.0 planned for 2027 |
| Mistral AI | French private company | from small to large MoE models | mixed: Apache 2.0, Modified MIT, proprietary | the European vendor closest to the frontier; little training disclosure |
Infrastructure and policy
- EuroHPC AI Factories: supercomputing centres opened to AI training and use
- IT4LIA, at CINECA in Bologna (with Austria and Slovenia), was among the first seven selected in Dec. 2024 (€1.5bn in total, EU + national funds)
- beware: IT4LIA is an AI Factory, not an AI Gigafactory: the Gigafactories call (for frontier-scale training) opened only in July 2026, with a Nov. 2026 deadline
- Data: ALT-EDIC’s LLMs4EU (March 2025, 3 years, 20+ countries) collects language resources for all EU languages, and targets sector-specific models
- Italian policy: the Italian AI Strategy 2024–2026 and Law 132/2025 call for technology “tailored to the Italian context” and open research artifacts
How good are Italian models?
- Measuring it is hard: translated English benchmarks are not enough
- ITA-Bench (CLiC-it 2024) mixes translated tasks with native Italian datasets
- Evalita-LLM (2025) uses native Italian tasks, and multiple prompts per task, since rankings are sensitive to prompt wording (leaderboard)
- Published numbers show that small Italian models can be useful, e.g. Velvet-2B reports 39.6 on Italian MMLU and 61.9–86.6 on ITA-Bench tasks…
- … but there is no robust evidence that Italian models outperform large multilingual open models (e.g. Qwen3, Gemma 4), let alone frontier ones, even on Italian
Leaderboard positions change every few months: when citing a rank, always write the snapshot date
Recurring issues of European open models
- Data: too little high-quality text in less-resourced languages (the very reason for LLMs4EU and for synthetic data)
- Compute: every project depends on a public supercomputer allocation (Leonardo, MareNostrum 5, JUWELS, Alps); an “open” model is not reproducible by anyone who lacks one
- Scale and timing: models trained from scratch up to 14B parameters, released months to years after comparable global open models; flagships “planned” or “pending”
- Maintenance: projects have finite funding (e.g. OpenGPT-X ended in 2025): who fixes, updates, and re-evaluates the models afterwards?
- Adoption: public-administration use is mostly aspirational in the sources, not a demonstrated large-scale deployment
These initiatives are valuable for research, openness, and language coverage; they are (still) not a production-grade alternative to global models. An EU organization can get operational control by running a global open-weights model on EU infrastructure
Engineering take-aways: pre-adoption checklist
The compliance unit is checkpoint + license version + code licenses + data licenses + deployment + intended use, not a brand name
| Question | What to check |
|---|---|
| exactly which artifact? | repository, checkpoint hash, release date, license version |
| commercial use? | Apache/MIT: yes; CC-BY-NC: no; custom licenses: read the use restrictions |
| on-premise use? | the license, not the availability of files (e.g. Llama 4 multimodal in the EU) |
| fine-tuning, distillation, merging? | whether derivatives inherit restrictions; license of each parent model |
| hosted service or redistribution? | whether serving an API counts as distribution (it does for Gemma 3); attribution and naming duties |
| geography or scale limits? | e.g. Llama 4: EU multimodal clause, 700M monthly users |
| training and fine-tuning data? | provenance, licenses (e.g. ODC-By), personal data |
| AI Act role? | are we becoming a GPAI provider (e.g. by fine-tuning and distributing)? does the open-source exemption apply? |
| reproducibility needed? | self-hosting: permissive weights suffice; audit or research: prefer fully open models (OLMo 3, Apertus) |
Mnemonic: weights → license → recipe → data → regulatory role: a model is only as open as the layer that matters for your use
Engineering take-aways: three scenarios
A UniBo lab, on-premise
- wants: local RAG/chat, fine-tuning on university material, reproducible experiments
- good fits: OLMo 3, Apertus (reproducibility); Gemma 4, Qwen3, gpt-oss, Mistral Apache models (weights only suffice); Minerva (Italian-centric research)
- ruled out: Llama 4 multimodal (EU clause)
An Italian startup reselling a fine-tune
- wants: fine-tune, host, sell the model
- good fits: Apache/MIT weights (Gemma 4, Qwen3, gpt-oss, DeepSeek-R1, Mistral Large 3, OLMo 3, Domyn Small)
- beware: R1 distills (Llama-based ones inherit Llama’s license); Gemma 3 (restrictions flow to customers); Teuken v0.6 (non-commercial)
A public administration
- wants: EU-controlled deployment and auditability
- auditability: Apertus, OLMo 3, Minerva
- operational control: any permissively licensed model on EU infrastructure (incl. Mistral, EuroLLM, Velvet, Domyn Small)
- beware: IT4LIA/CINECA provides compute, not a model license
Agentic Technique Selection Criteria
Which technique? Recall
- Recall the technique selection from the RAG lecture: prompting, tools and agents, RAG, skills and workflows, fine-tuning
- each option adds effort to the previous ones, and complexity to the system
- choose by asking what is missing (knowledge, actions, a reliable procedure, a style), cf. the intuitive example
- From the governance viewpoint, what matters are the trade-offs (next slide): cost, control, compliance, and time-to-market
Which technique? Trade-offs
| Technique | Quality | Cost | Control | Compliance | Time-to-market |
|---|---|---|---|---|---|
| Prompting | good, if the model knows enough | low (but long prompts cost tokens at each request) | high: prompts are versioned text | easy to audit | fastest |
| Tools / agents | high for tasks needing actions or live data | medium (more requests per task) | medium: behaviour is less predictable | needs least privilege and logging | medium |
| RAG | high for knowledge-intensive tasks | medium (indexing + longer prompts) | high: knowledge base is inspectable and updatable | data stays in your store; access control needed | medium |
| Skills | high, if the agent picks the right skill | low–medium | medium: the agent decides when to apply them | depends on the tools the skill allows | fast (write a document) |
| Workflows | high and consistent | medium | highest: steps are fixed by the engineer | easy to audit step by step | slow (more code) |
| Fine-tuning | highest for narrow tasks, if data suffice | high (data, training, re-training at each model update) | low–medium: behaviour baked into weights | training data must be lawful; license must allow it | slowest |
- These options combine: e.g. a workflow whose steps use prompting, RAG, and tools
- Empirically, RAG tends to outperform fine-tuning at injecting new knowledge (Ovadia et al., 2023), while fine-tuning is better at shaping form
Recall the rule of thumb: start with prompting, measure, and add complexity only when evaluations show that it is needed
Model Selection Criteria
Which model? The general concept
- Choosing a model is a governance decision, since it affects all five dimensions at once:
- quality (capabilities), cost (price per token, or hardware), control (open weights? version pinning? deprecation?), compliance (license, provider’s jurisdiction and data policies), time-to-market (availability, ecosystem)
- It requires information about models, which comes from:
- their documentation (model cards, system cards, licenses, terms of service)
- public evaluations (benchmarks, leaderboards)
- your own evaluations on the task at hand
- It is not a one-off decision: models are updated, deprecated, and surpassed every few months, so the choice must be re-assessed periodically (and made reproducible)
(cf. model zoos in the LLM-as-a-Service lecture)
Model documentation: model cards, system cards, datasheets
- Model cards: recall them from the model zoos of the LLM-as-a-Service lecture (Mitchell et al., 2019; Hugging Face’s guide); here, what matters is what they say about governance (below)
- Datasheets for datasets (Gebru et al., 2021): the same idea, for training data (motivation, composition, collection, recommended uses)
- System cards: longer reports published by frontier providers for each model release, focusing on safety evaluations, red-teaming, and mitigations
- e.g. OpenAI’s and Anthropic’s system cards
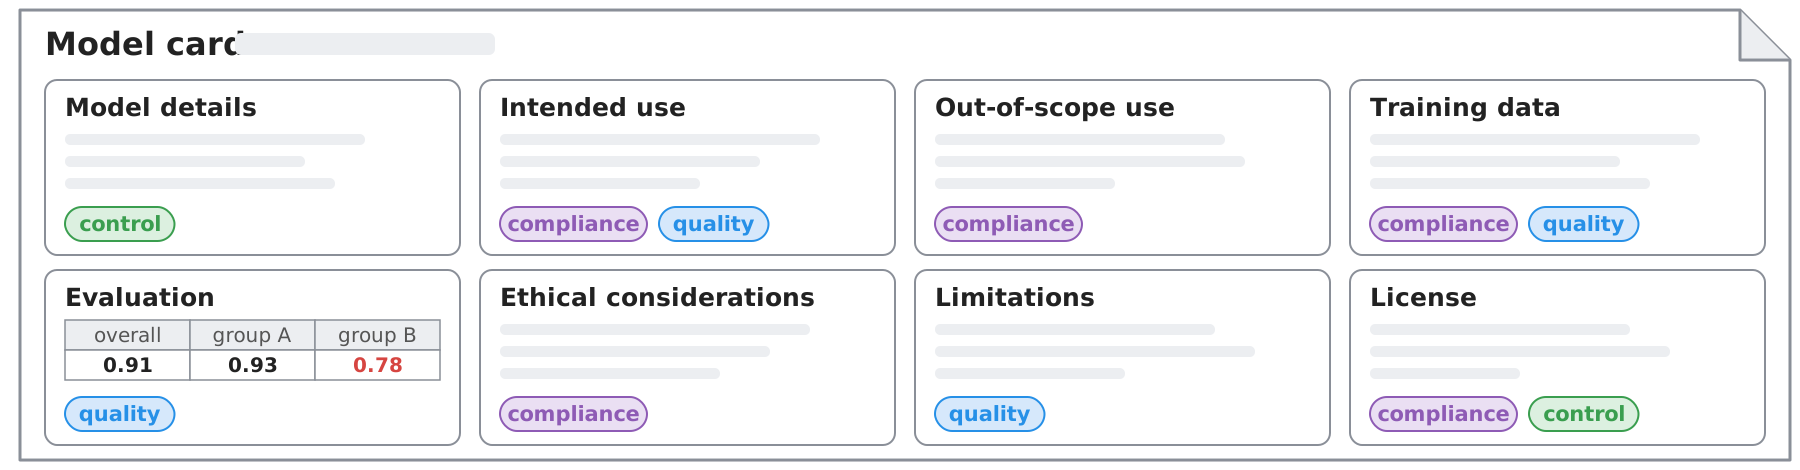
- What to look for, as an engineer: license, languages, context window, knowledge cut-off, intended uses (does yours fit?), known limitations, and evaluations relevant to your task
Measuring general capabilities: frontier benchmarks
As models saturate classic benchmarks, new ones try to measure what models cannot (yet) do:
- ARC-AGI (Chollet, 2019): intelligence as skill-acquisition efficiency, measured on visual puzzles that are easy for humans, and require abstracting rules from a few examples
- ARC-AGI-2 (2025) raised the difficulty; the ARC Prize 2025 grand prize went unclaimed
- ARC-AGI-3 (March 2026) is interactive: cf. the agentic benchmarks of the agents lecture, and the leaderboard below
- Humanity’s Last Exam (Phan et al., 2025): 2,500 expert-written questions across disciplines, designed to be un-googleable
- best models went from single digits (early 2025) to ~60% (cf. Artificial Analysis, September 2026)
- METR’s time horizon (Kwa et al., 2025): the length of tasks (in human-expert time) that an agent completes with 50% success
- doubling every ~7 months over 2019–2025 (212 days, in the original paper), and faster since 2023: ~4 months (129 days, METR’s Time Horizon 1.1 fit, cf. live measurements)
- Aggregated views: the Stanford AI Index 2026 describes a jagged frontier: models winning maths olympiad gold medals, yet failing at reading analog clocks
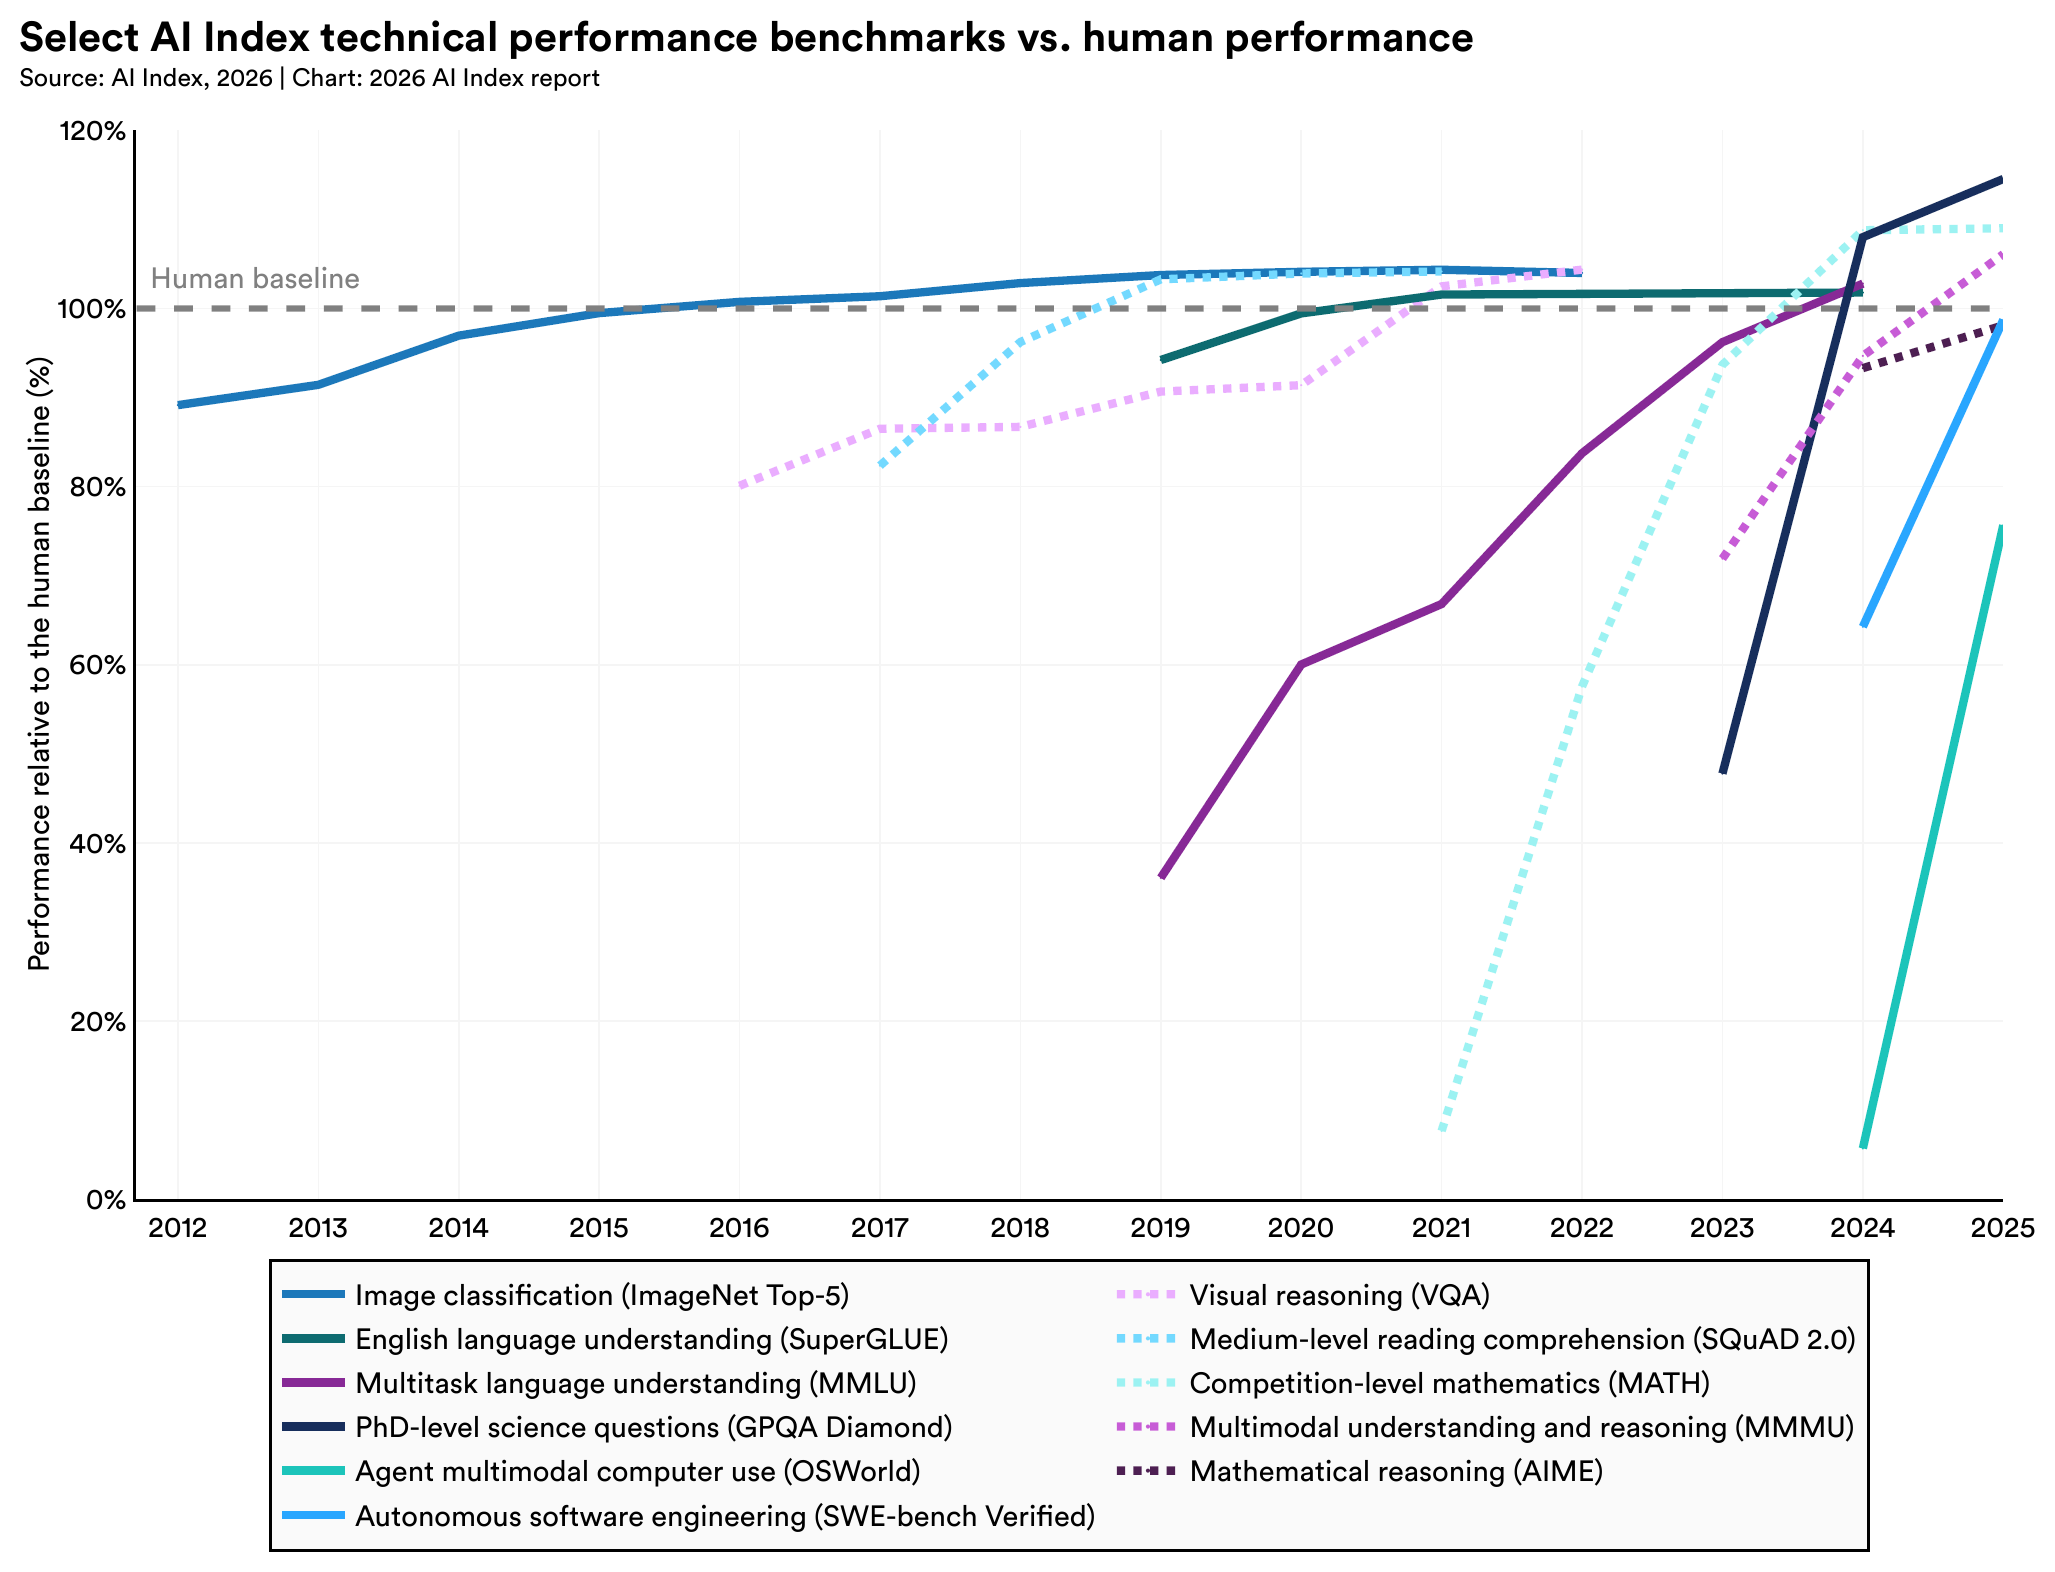
Source: Stanford AI Index 2026, ch. 2, Figure 2.1.1 (CC BY-ND 4.0)
Engineering take-away: frontier benchmarks tell you where the state of the art is, not whether a model is good for your task
Frontier benchmarks: METR’s time horizons
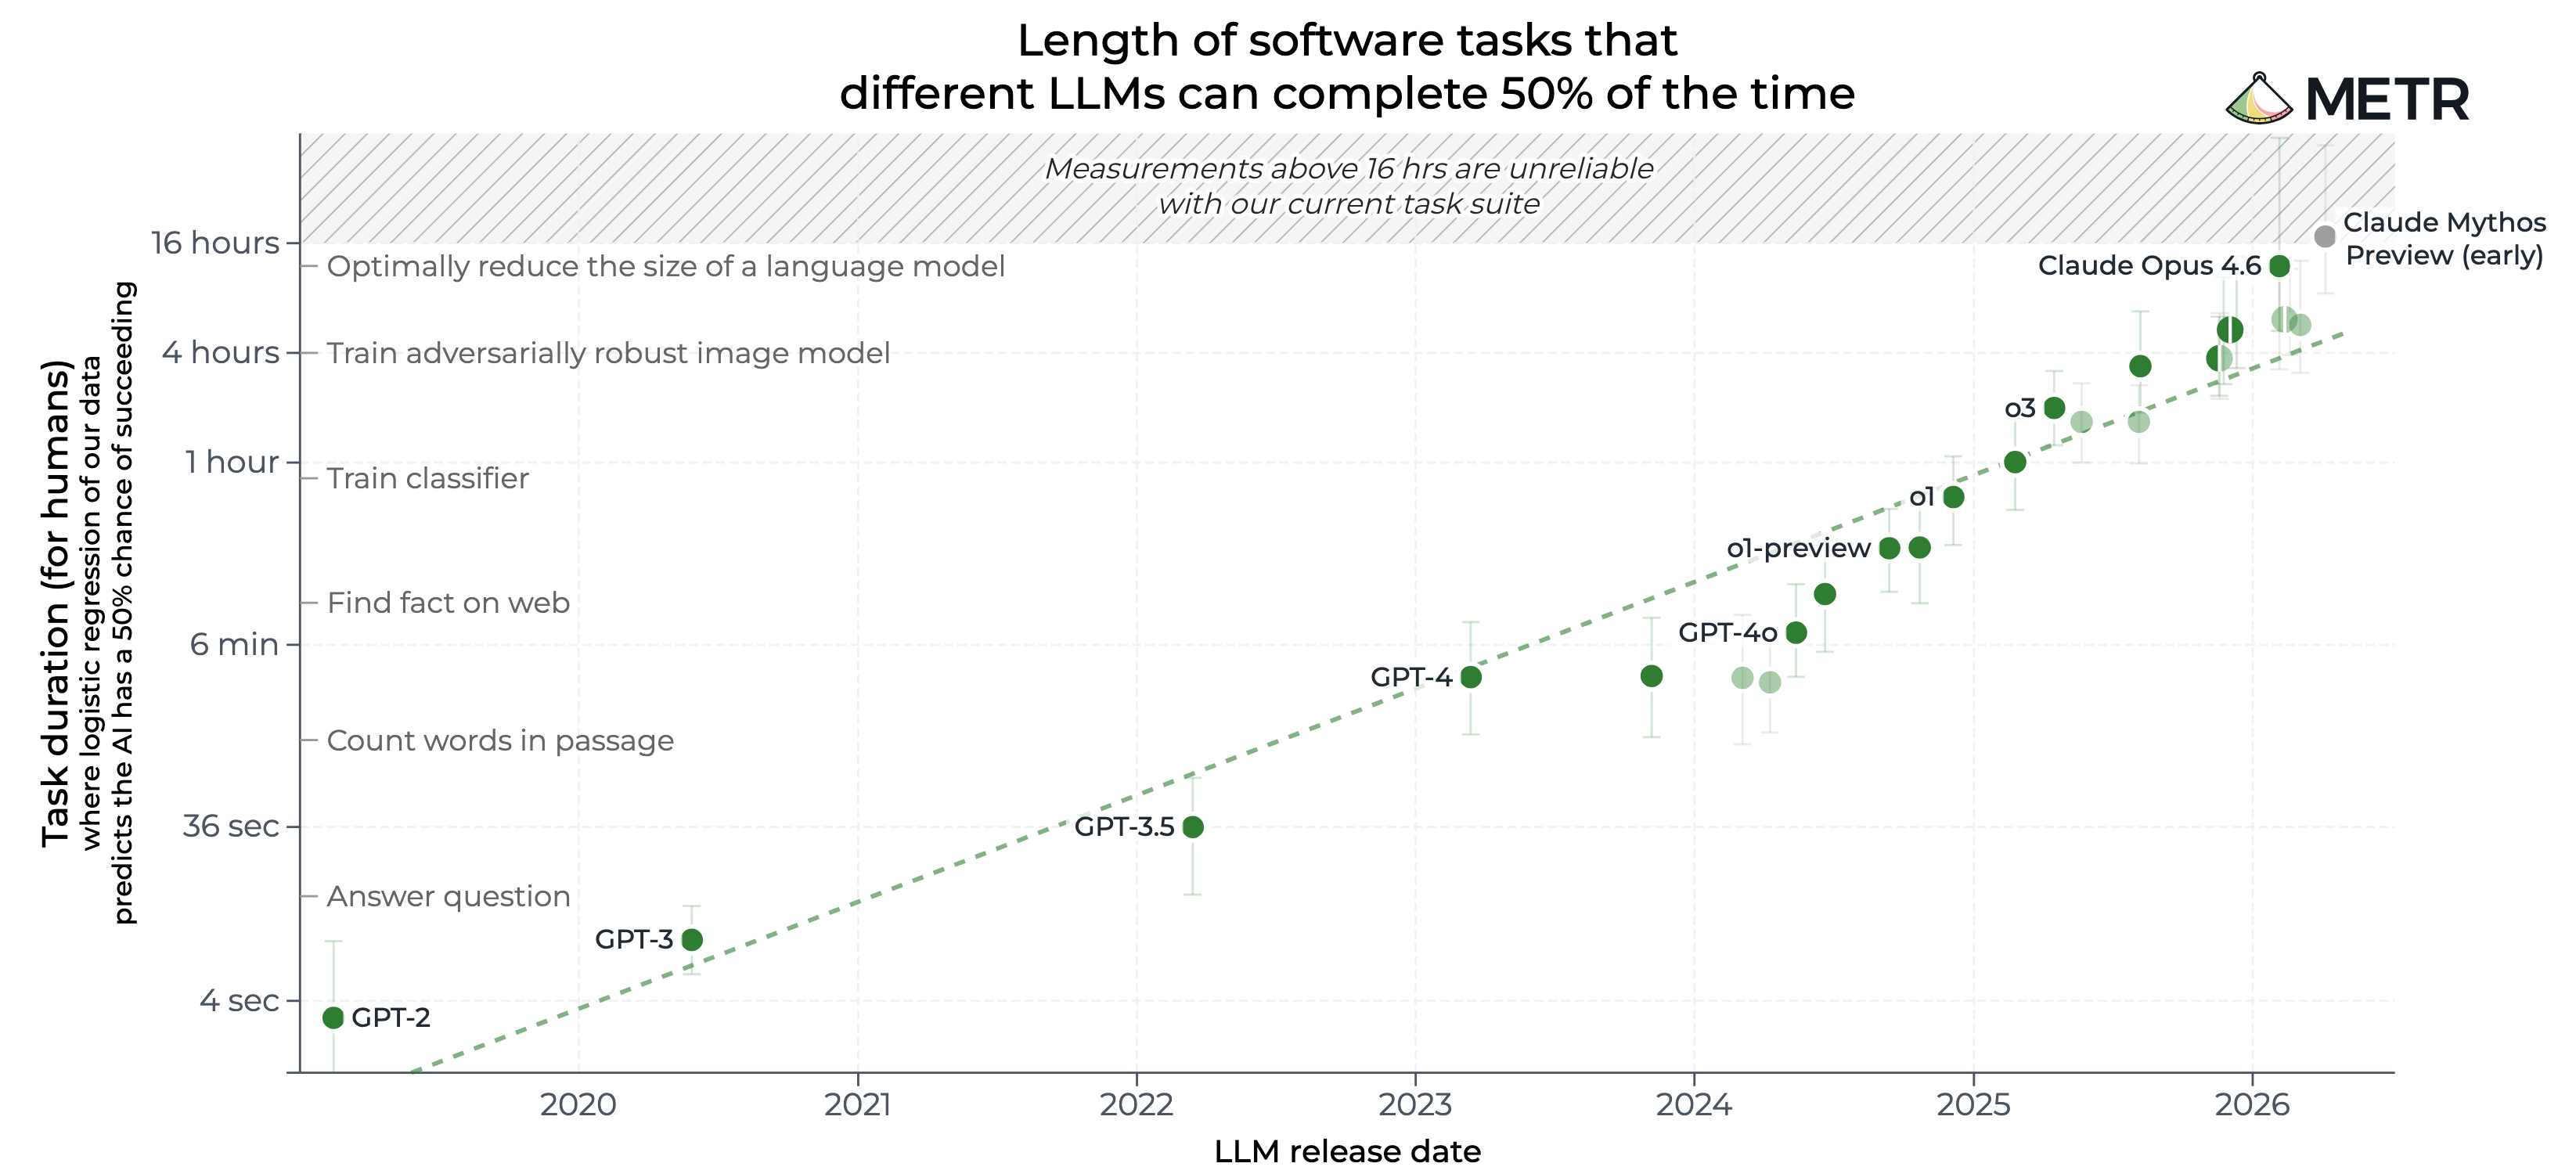
- E.g. the 50% time horizon of Claude Mythos Preview (April 2026) is ~17 hours, at the limit of what METR’s task suite can measure
- Caveats: software tasks only, 50% success (the 80% horizon is much shorter), wide confidence intervals
Source: METR, time horizons, retrieved October 2026
Frontier benchmarks: METR’s time horizons (cont.)
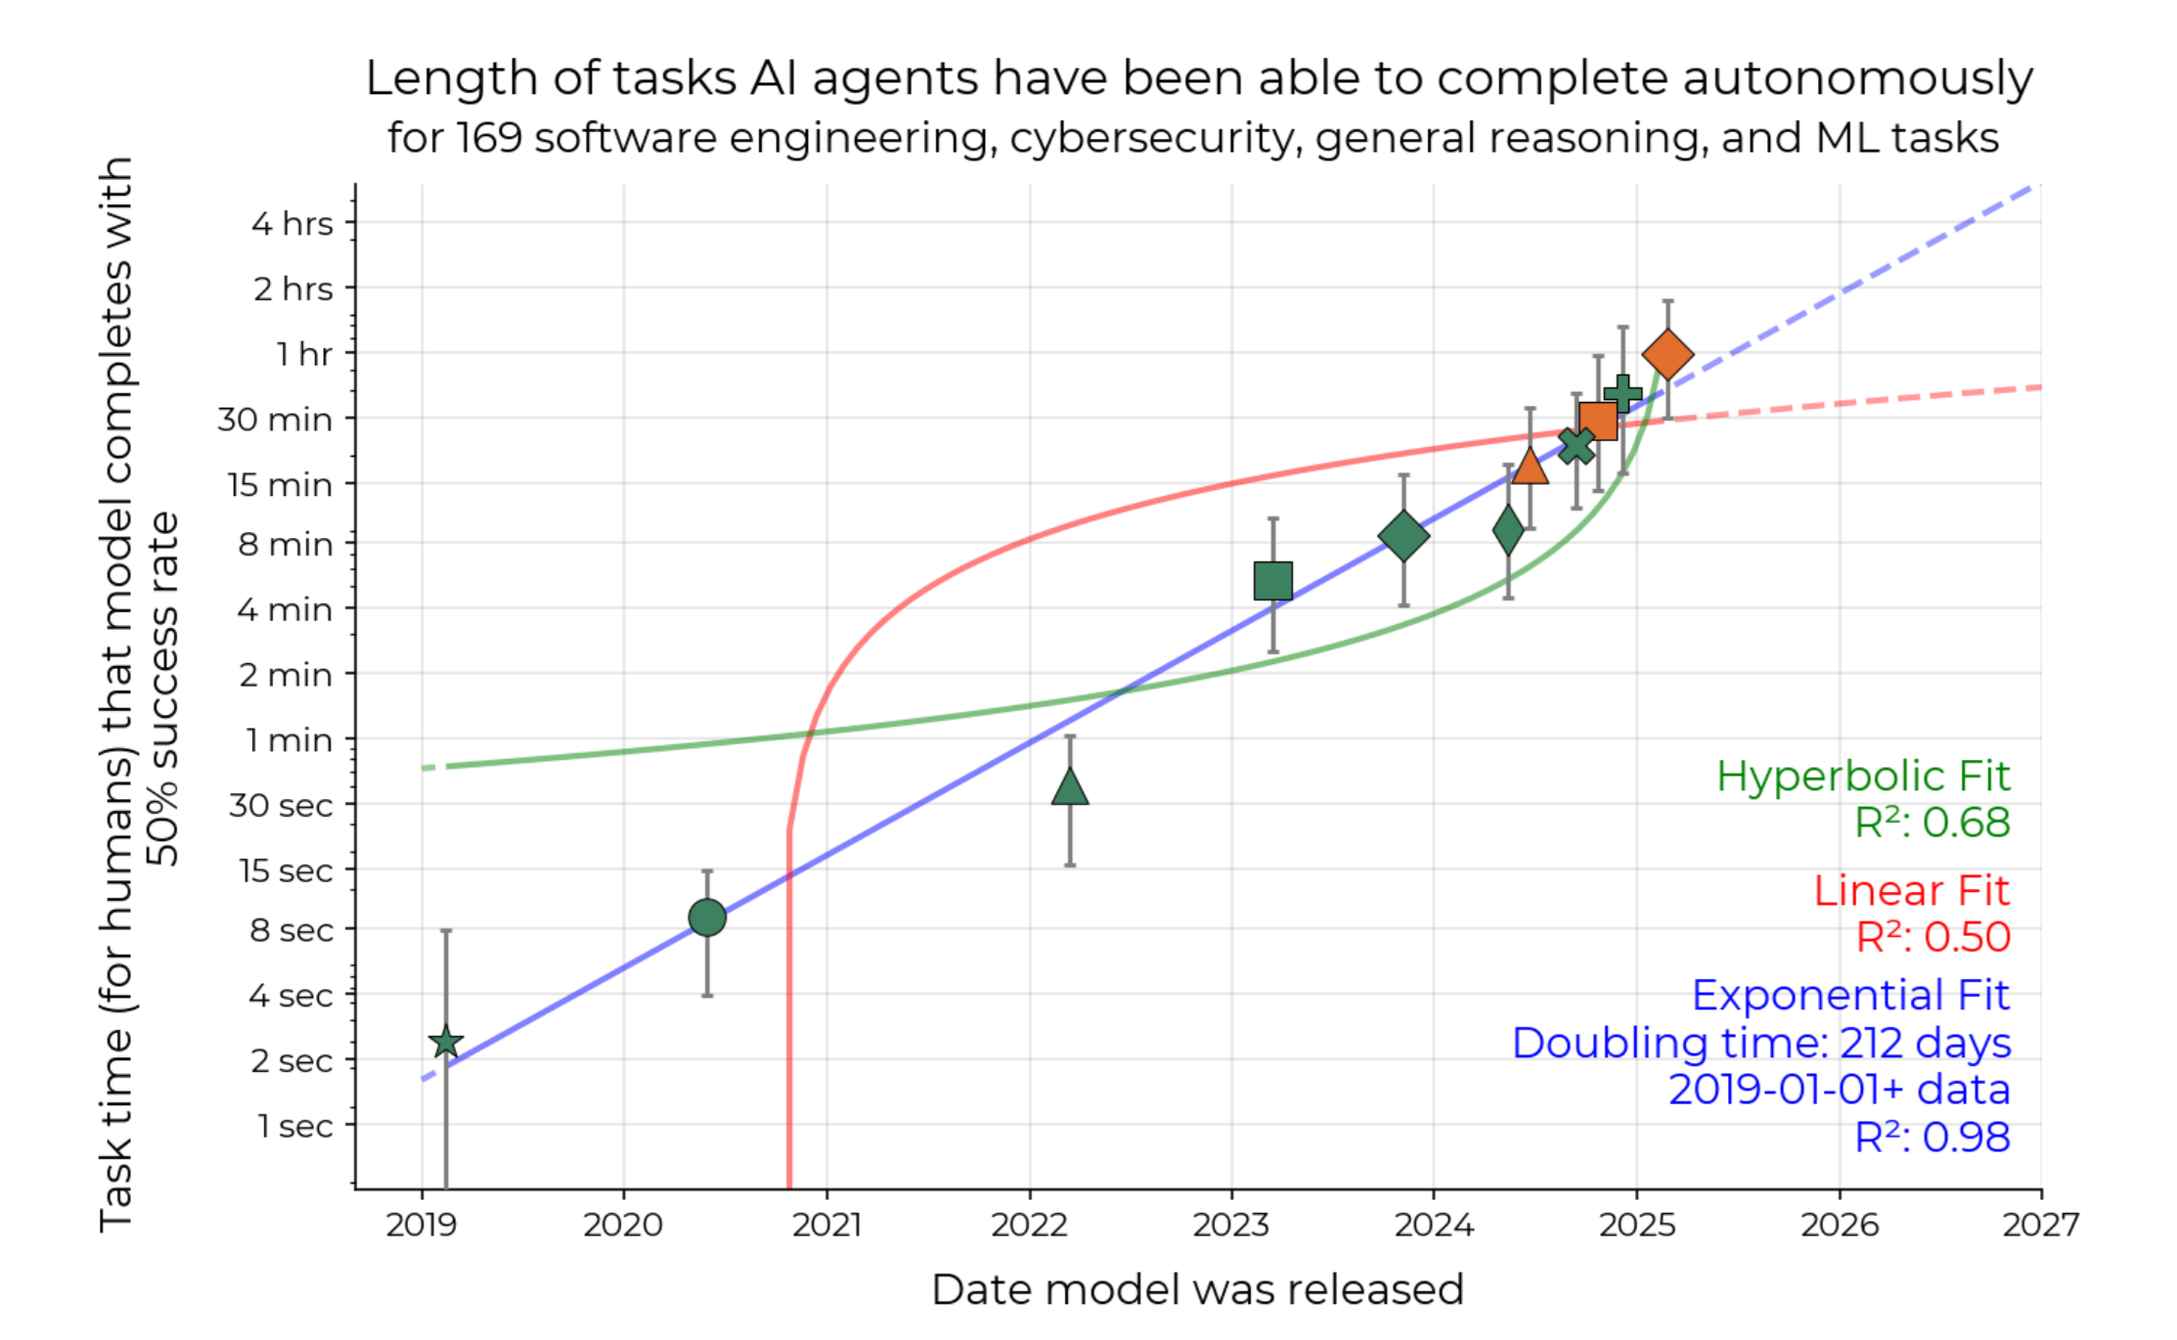
- The original fit: doubling every 212 days (2019–2025)
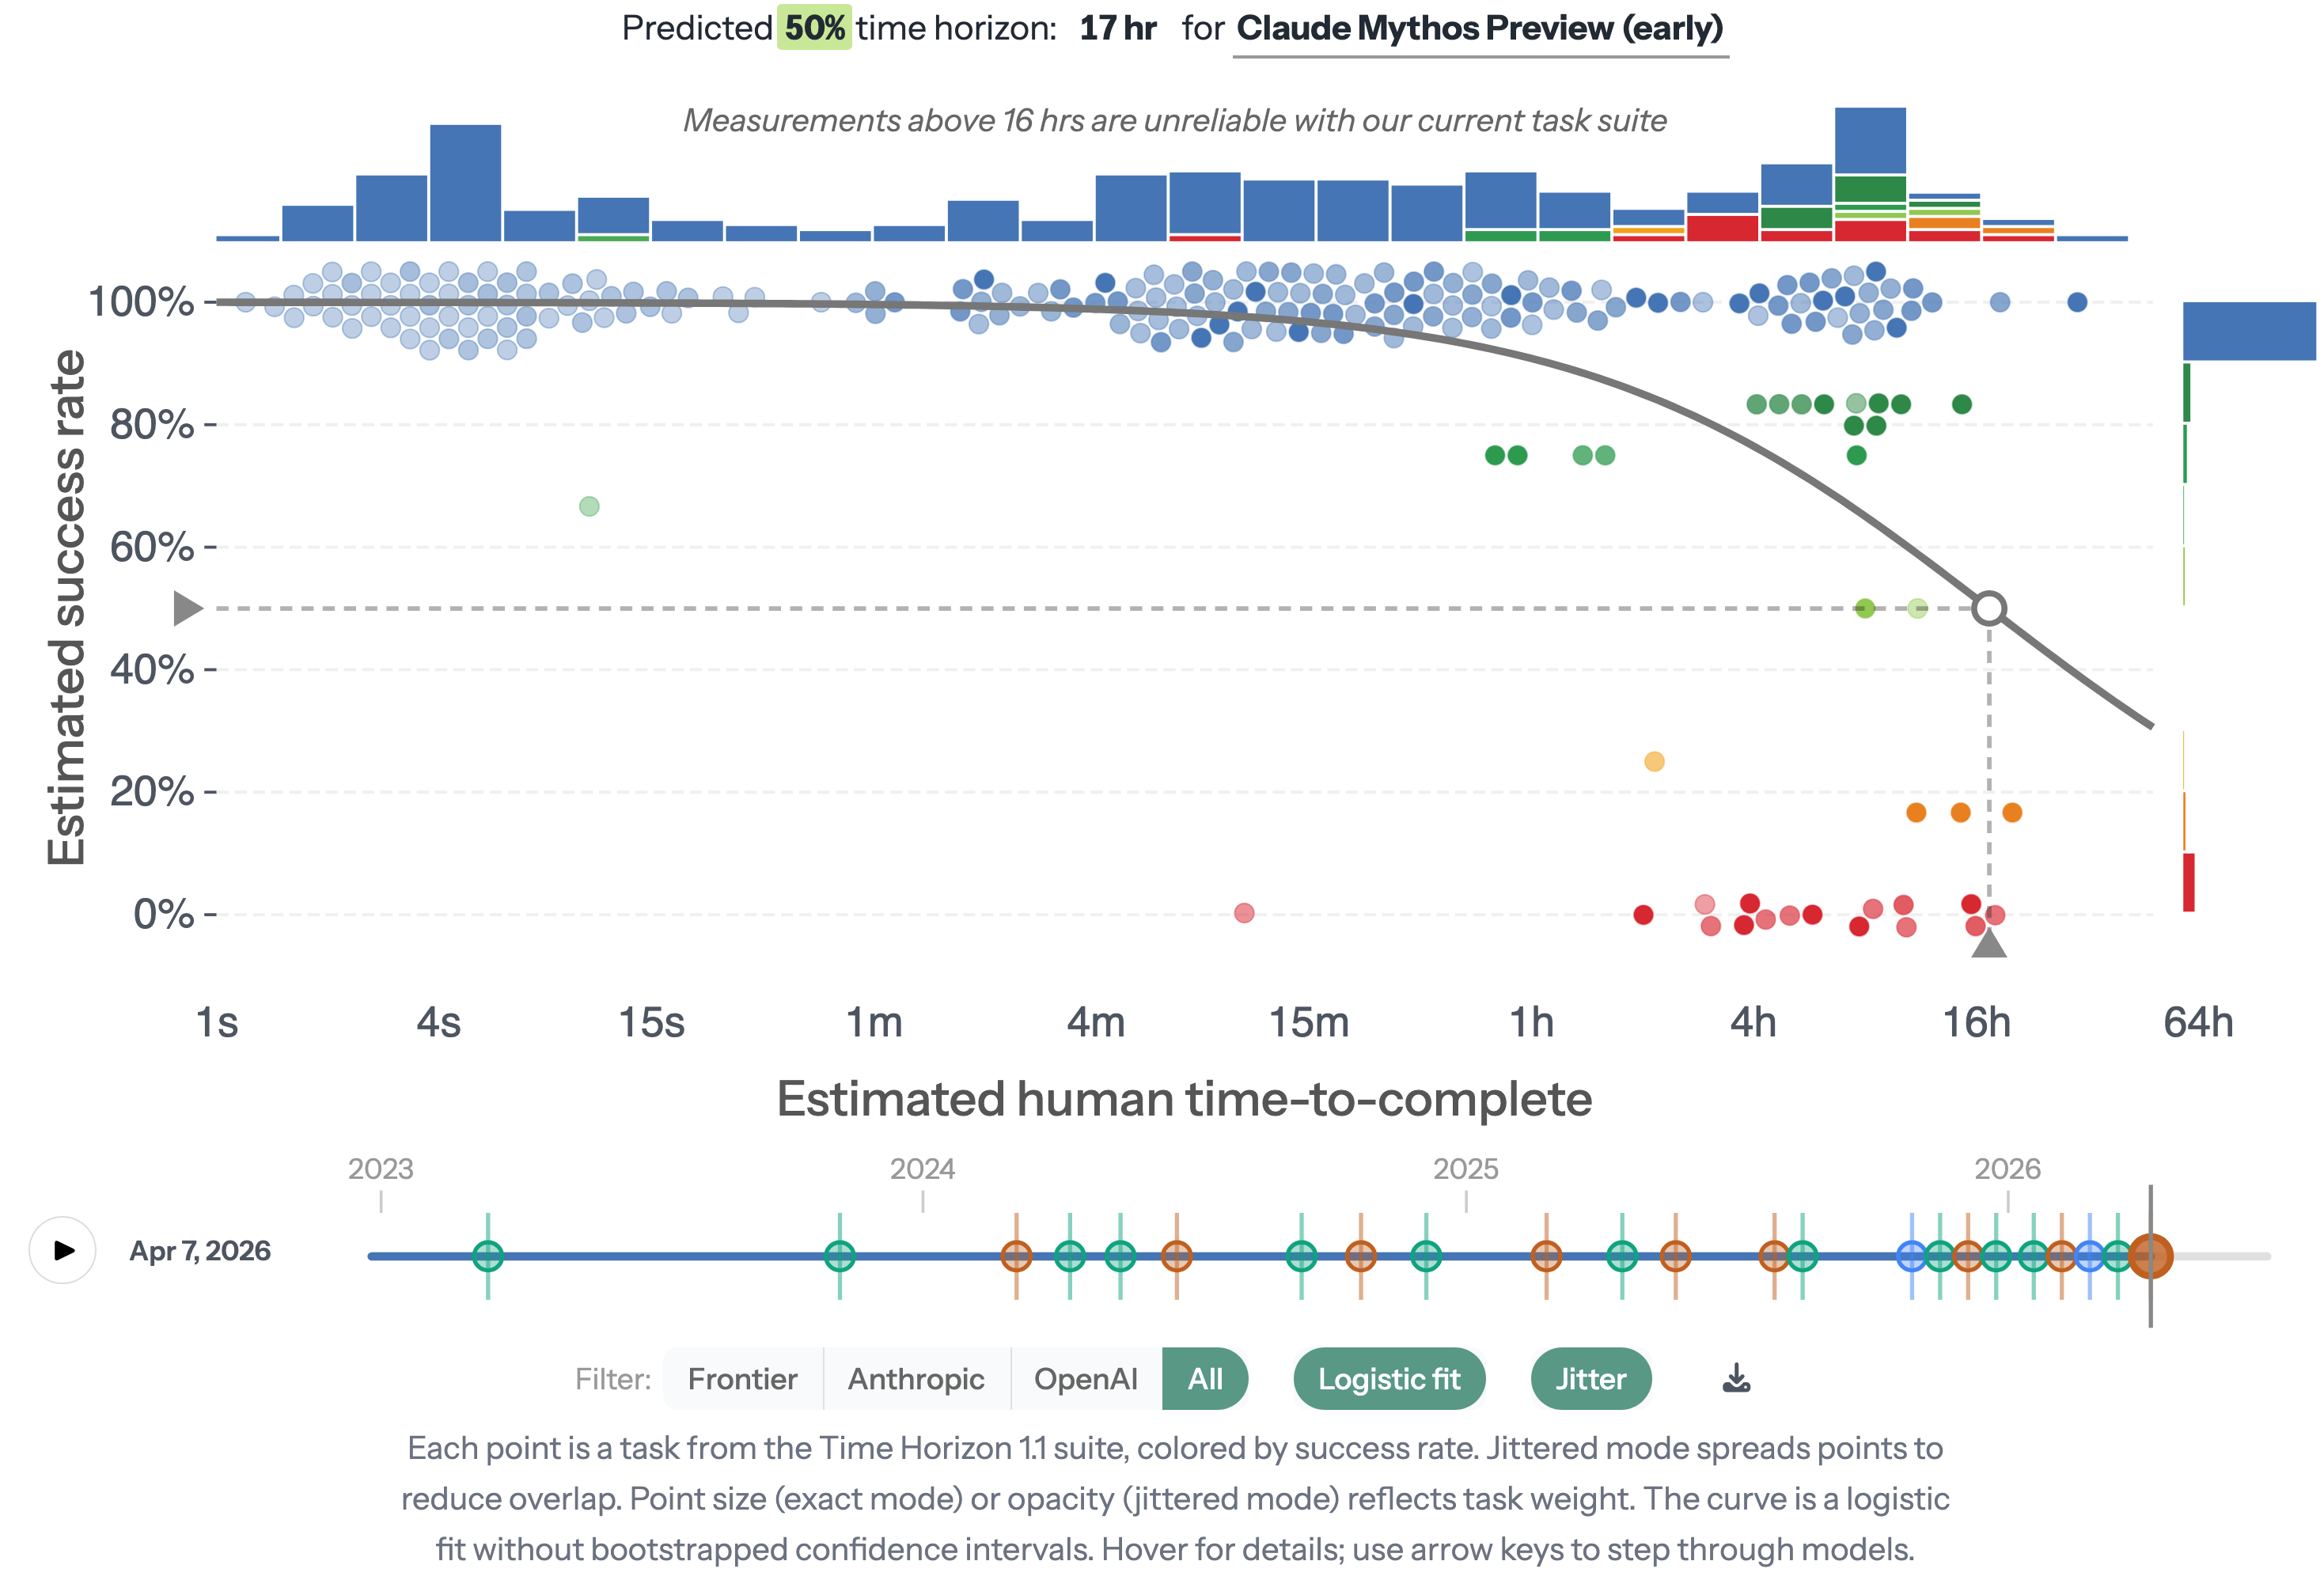
- How a horizon is computed: success rate vs. human task length, then a logistic fit, read at 50%
Source: METR, time horizons, retrieved October 2026
Frontier benchmarks: the ARC-AGI-3 leaderboard
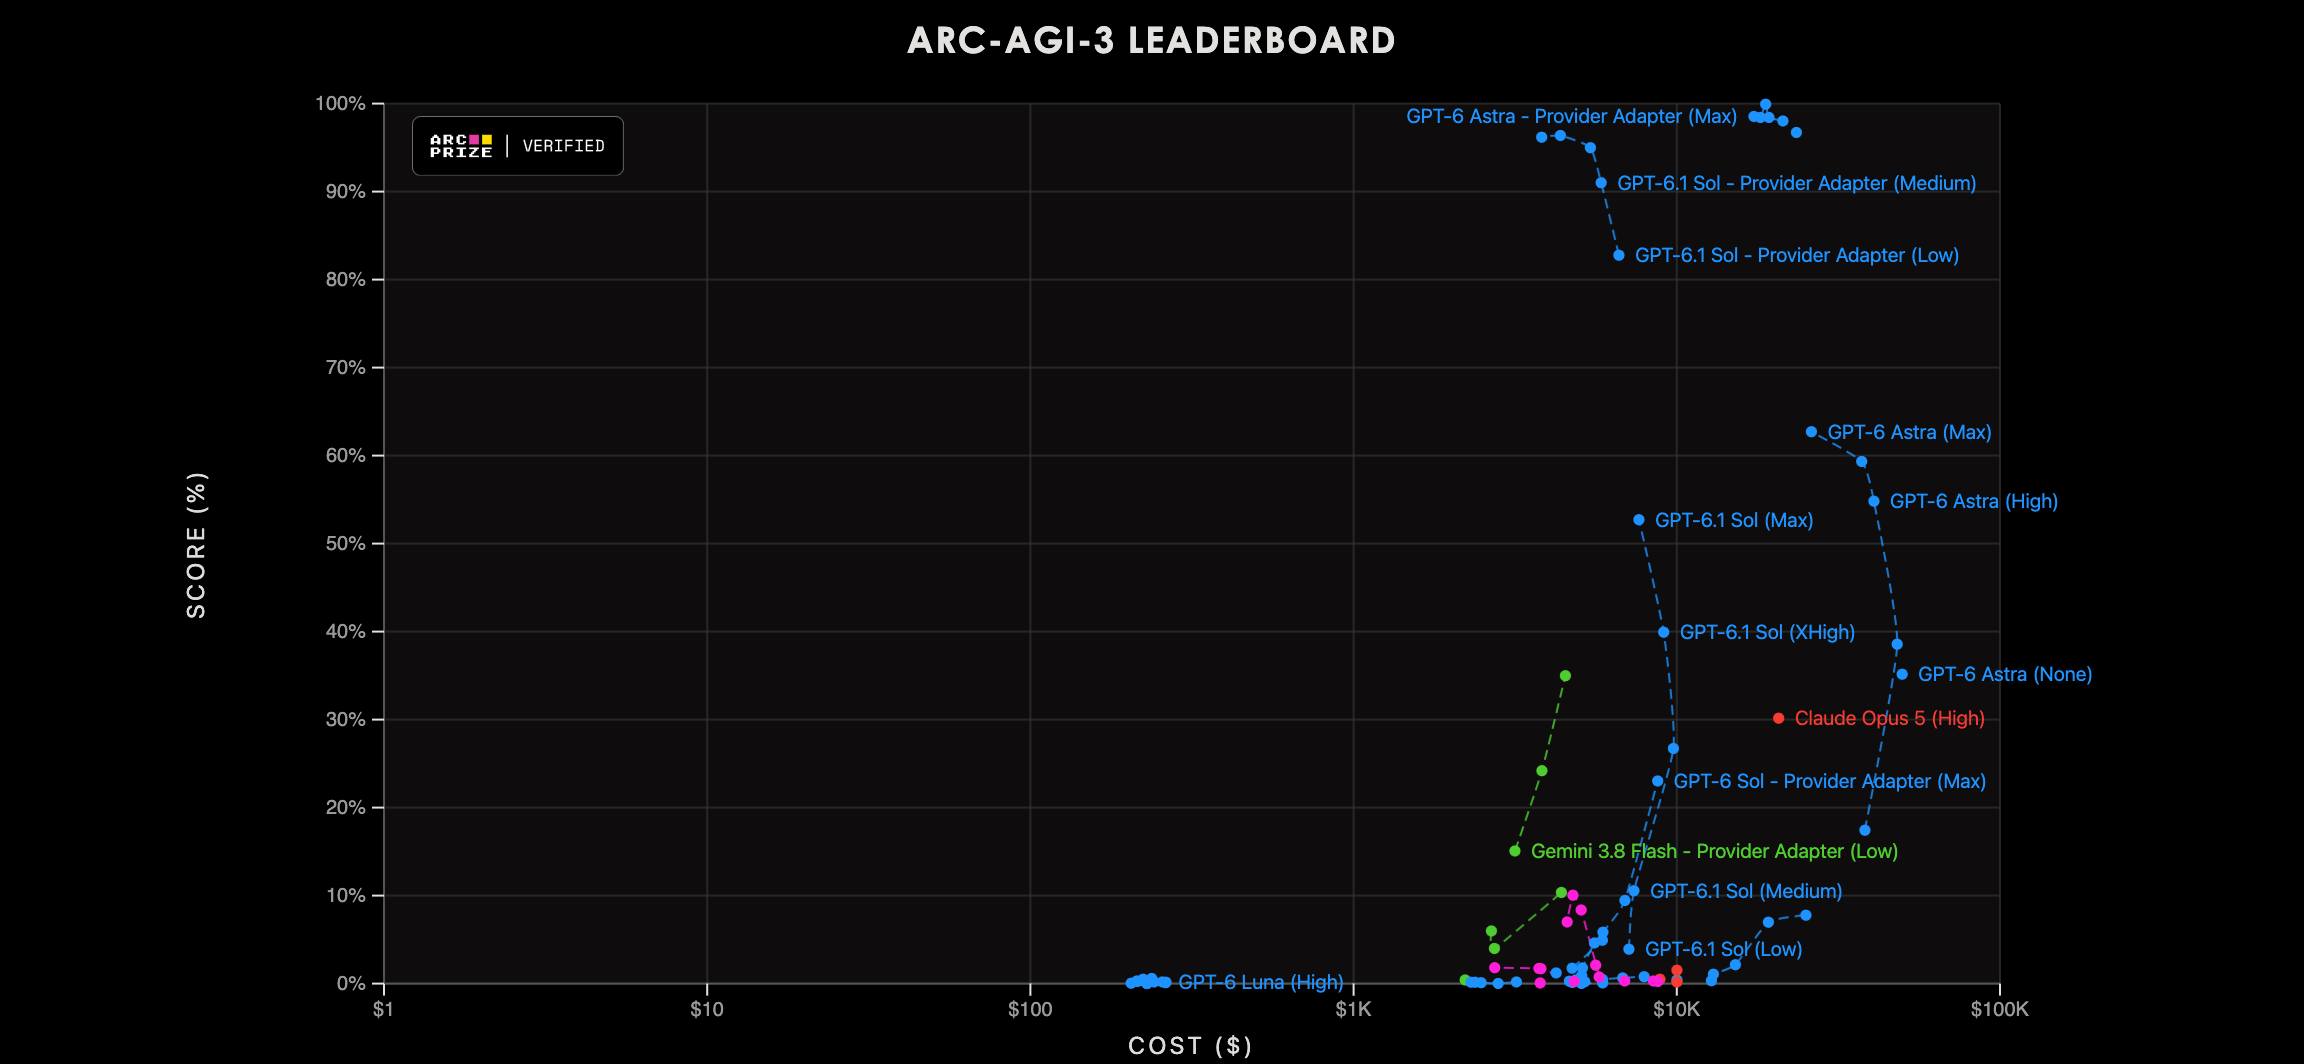
- From < 1% at launch (March 2026) to 62.7% with the standard harness, and ~99% with a general-purpose harness (keeping reasoning state, compacting the conversation), in 6 months
- at a cost of thousands to tens of thousands of dollars per full run; humans solve all environments
Source: ARC Prize leaderboard, retrieved October 2026
How to choose a model for a given task?
Hard constraints (filter)
- Deployment: on-premise (hardware available?) or on-cloud (budget available?)
- Data protection: can the data leave your premises? which jurisdiction? (cf. GDPR)
- License: is the intended use (e.g. commercial) permitted?
- Modalities: text only? images? audio?
- Capabilities: tool calling? structured output? reasoning?
- Context window: will prompts + documents + history fit?
- Languages: e.g. is Italian supported well enough?
Soft criteria (rank)
- quality on your task (see next slide)
- latency (time to first token, tokens per second)
- cost per request (tokens × price, or hardware amortization)
- stability of the offer (will the model be deprecated soon?)
- ecosystem (client libraries, documentation, community)
Rule of thumb: start from the smallest/cheapest model satisfying the hard constraints, measure its quality on your task, and move to bigger models only if needed
How to evaluate models?
1. Public benchmarks and leaderboards (generic, cheap to consult)
- benchmarks: fixed datasets + metrics for some capability
- leaderboards: rankings aggregating benchmark results or human preferences
- e.g. Arena (formerly Chatbot Arena / LMArena: humans blindly compare pairs of answers, cf. Chiang et al., 2024; but see also the critique by Singh et al., 2025), Artificial Analysis (quality vs. price vs. speed)
- caveats:
- data contamination: benchmark items may have leaked into training data (cf. Xu et al., 2024)
- saturation: top models all score near 100%, so benchmarks stop discriminating (e.g. Hugging Face retired its Open LLM Leaderboard in 2025)
- Goodhart’s law: once a benchmark becomes a target, it stops being a good measure
- benchmarks measure generic skills, possibly not the ones your task requires
2. Task-specific evaluation (the one that really matters)
- run each shortlisted model on your test dataset, with your scorers, as in the validating lecture (deterministic scorers first, LLM-as-a-Judge where code can’t help)
- measure latency and cost too (both reported in the API responses’ metadata, e.g.
usage)
Exercise 1: Comparing Models on the Running Example (pt. 1)
Goal: the admission committee wants to pick the model to be used for letter scoring (cf. Example 1 of the Prompt Engineering lecture), based on evidence rather than on hype
Code: put your solution in
snippets/lecture_governance/exercise1/oflab-snippets, and run it viapoetry run python -m snippets -l governance -x 1
TO-DO List
- Shortlist 3 models, e.g.:
- one small free model on Open Router,
- one larger (possibly free) model on Open Router,
- one local model via Ollama (if your hardware allows it)
- Run the letter-scoring system on all 3 letters of the running example, 5 times per letter per model
- the script is already parametric w.r.t. the model: just change
OPENAI_MODEL(andOPENAI_BASE_URL=http://localhost:11434/v1for Ollama)
- the script is already parametric w.r.t. the model: just change
- For each model, collect:
- the scores (average, and variance across the 5 runs: is the model consistent?)
- the agreement among models (do they rank candidates in the same way?)
- the number of failures (e.g. invalid JSON, validation errors)
- latency (wall-clock time per request) and tokens used (from
response.usage), hence cost
- Summarize the results in a table, and motivate your choice
Exercise 1: Comparing Models on the Running Example (pt. 2)
Decision points and hints
- Same idea as step 5 of Exercise 2 of the validating lecture, now with costs and latency; a plain script, as DeepEval or MLflow score one system at a time (MLflow would work too: one run per model)
- How to automate the runs?
- e.g. a script looping over models × letters × repetitions, writing one row per run in a CSV file
- reuse the caching mechanism of Exercise 1 of the LLM-as-a-Service lecture? (careful: caching would hide the variance!)
- How to measure time?
- e.g.
time.perf_counter()before and after the request
- e.g.
- How to compute costs?
score_letter(...)only returns the parsedLetterInfo: adapt it to also return the wholeresponse(or itsusage)- multiply
usage.prompt_tokensandusage.completion_tokensby the prices listed in the zoo (Open Router also reportsusage.costdirectly)
- How to deal with rate limits of free models?
- reuse the retry mechanism of Exercise 2 of the LLM-as-a-Service lecture
- What if models disagree?
- which one is right? you need a reference: e.g. score the letters yourself, and compare each model against your scores
How to test it?
- the table should contain 3 models × 3 letters × 5 runs = 45 rows (minus failures, which should be counted, not hidden)
- re-running the script with a different temperature (e.g.
0vs.1) should visibly affect the variance
Solution: a walkthrough follows in the next (vertical) column — try on your own first!
Exercise 1: Comparing Models on the Running Example — Solution
⚠️ The walkthrough of a possible solution is about to start
- do not proceed until you have attempted the exercise on your own
- press → to skip it, ↓ to see it
- the code is on the
masterbranch oflab-snippets(while you cloned theexercisesbranch)
Exercise 1 — Solution: Shortlist, Reference, and Clients
Step 1: shortlist 3 models (and fix a reference to compare them against)
# step 1: the shortlist (free models are rate-limited: retries below)
DEFAULT_MODELS = ["google/gemma-4-26b-a4b-it:free", "nvidia/nemotron-3-super-120b-a12b:free", "llama3.2@http://localhost:11434/v1"]
REPETITIONS = int(os.environ.get("REPETITIONS", 5))
TEMPERATURE = os.environ.get("TEMPERATURE")
# the reference: the committee's OWN scores, by reading the letters (without it, one can tell whether models agree, not who is right)
REFERENCE = {"mario-rossi": 5, "jean-dupont": 3, "mohammed-ali": 2}
OUTPUT = Path(os.environ.get("COMMITTEE_OUTPUT", "output")) / "model-comparison.csv"


def client_for(model: str) -> tuple[OpenAI, str]:
    """e.g. 'llama3.2@http://localhost:11434/v1' -> a client for Ollama, and 'llama3.2'."""
    name, _, url = model.partition("@")
    return OpenAI(base_url=url or base_url, api_key=api_key if not url else "local", max_retries=0), name
- models are passed on the command line as
MODEL(Open Router) orMODEL@BASE_URL(e.g. Ollama): one script, many providers, thanks to OpenAI-compatible APIs REFERENCE= the committee’s own scores: without it, one can tell whether models agree, not who is rightmax_retries=0: retries are handled explicitly (next slide)base_url,api_key: imported from Example 1 of the Prompt Engineering lecture (i.e.OPENAI_BASE_URL,OPENAI_API_KEY)- env vars:
REPETITIONS(runs per letter),TEMPERATURE(default: the provider’s),COMMITTEE_OUTPUT(directory of the CSV file)
Exercise 1 — Solution: Scoring a Letter, Keeping the Usage
Step 2: adapt
score_letter(...)to return the whole response, not just the parsedLetterInfo
def score_letter(client: OpenAI, model: str, letter_text: str):
    """As in Example 1, but returns the WHOLE response (i.e. also its usage), not just the parsed LetterInfo."""
    options = dict(temperature=float(TEMPERATURE)) if TEMPERATURE else {}
    return with_retries(lambda: client.chat.completions.parse(  # retries upon rate limits (cf. Exercise 2 of the LLM-as-a-Service lecture)
        model=model,
        messages=[
            dict(role="system", content=general_instructions),
            dict(role="user", content=f"Score the following letter:\n\n<letter>\n{letter_text}\n</letter>"),
        ],
        response_format=LetterInfo,
        **options,
    ), retries=5, initial_delay=5)
- same prompt and schema as Example 1 of the Prompt Engineering lecture (imported, not copied): we compare models, not prompts
- the response carries
usage, hence tokens and cost with_retries(from Exercise 2 of the LLM-as-a-Service lecture) copes with rate limits of free models- no caching: it would hide the variance
Exercise 1 — Solution: One Run = One Row
Steps 2–3: run once, and collect score, failures, latency, tokens, and cost
def run_once(model: str, candidate: str, repetition: int) -> dict:
    """Step 2-3: one run, as a row of the CSV file. Failures are rows too: they must be counted, not hidden."""
    client, name = client_for(model)
    row = dict(model=model, candidate=candidate, repetition=repetition, score=None, error=None, latency=None, prompt_tokens=None, completion_tokens=None, cost=None)
    start = time.perf_counter()
    try:
        response = score_letter(client, name, data.letter(candidate).read_text())
        row["latency"] = round(time.perf_counter() - start, 2)  # wall-clock time, retries included
        row["score"] = response.choices[0].message.parsed.score  # may fail, e.g. upon refusals or invalid JSON
        row["prompt_tokens"], row["completion_tokens"] = response.usage.prompt_tokens, response.usage.completion_tokens
        row["cost"] = getattr(response.usage, "cost", None)  # in USD, reported by Open Router (not part of OpenAI's API)
    except Exception as e:
        row["error"] = f"{type(e).__name__}: {e}"[:200]
    return row
- failures (refusals, invalid JSON, validation errors) are rows too: counted, not hidden
- latency via
time.perf_counter(): wall-clock, retries included (what users would actually wait) usage.costis an Open Router extension: elsewhere, multiply tokens by the prices in the zoo
Exercise 1 — Solution: Summarising per Model
Step 4: one line per model, comparing mean ± sd against the reference
def summarise(rows: list[dict]) -> list[dict]:
    """Step 4: one line per model."""
    summary = []
    for model in dict.fromkeys(row["model"] for row in rows):  # models, in order of appearance
        ok = [row for row in rows if row["model"] == model and row["error"] is None]
        scores = {c: [row["score"] for row in ok if row["candidate"] == c] for c in REFERENCE}
        means = {c: statistics.mean(s) for c, s in scores.items() if s}
        summary.append(dict(
            model=model,
            **{c: f"{means[c]:.1f} ± {statistics.pstdev(s):.1f}" if s else "n/a" for c, s in scores.items()},  # consistency
            error=round(statistics.mean(abs(row["score"] - REFERENCE[row["candidate"]]) for row in ok), 2) if ok else None,  # w.r.t. the reference
            ranking=" > ".join(sorted(means, key=means.get, reverse=True)),  # agreement among models: compare these
            failures=sum(row["model"] == model for row in rows) - len(ok),
            latency=round(statistics.mean(row["latency"] for row in ok), 1) if ok else None,
            tokens=sum((row["prompt_tokens"] or 0) + (row["completion_tokens"] or 0) for row in ok),
            cost=round(sum(row["cost"] or 0 for row in ok), 4),
        ))
    return summary
statistics(Python’s standard library):mean, andpstdev(population standard deviation)dict.fromkeys(...): the models, de-duplicated but in order- standard deviation per letter → consistency of each model
- mean absolute error w.r.t. the reference → who is right
- ranking of candidates → agreement among models (compare the rankings across lines)
- failures, latency, tokens, cost → the other dimensions of the choice
Exercise 1 — Solution: The Main Loop
Automate the runs: models × letters × repetitions, raw data to CSV, summary as a table
if __name__ == "__main__":
    models = sys.argv[1:] or DEFAULT_MODELS
    rows = []
    for model in models:
        for candidate in REFERENCE:
            for repetition in range(REPETITIONS):
                rows.append(row := run_once(model, candidate, repetition))
                outcome = row["error"] or f"score {row['score']} in {row['latency']}s"
                print(f"# {model} | {candidate} #{repetition + 1}: {outcome}")

    OUTPUT.parent.mkdir(parents=True, exist_ok=True)
    with OUTPUT.open("w", newline="") as f:  # raw data: one row per run, for further analysis
        writer = csv.DictWriter(f, fieldnames=list(rows[0]))
        writer.writeheader()
        writer.writerows(rows)
    print(f"\nRuns written to {OUTPUT}, reference scores: {REFERENCE}\n")
    print(markdown(summarise(rows)))
- 3 models × 3 letters × 5 runs = 45 rows, saved in
output/model-comparison.csvfor further analysis csv.DictWriter(standard library): writesdicts as CSV rows, one column per key- the summary is printed as a Markdown table (by
markdown(...), a tiny helper in the same file): ready to be pasted into the decision record of Exercise 2 - try
TEMPERATURE=0vs.TEMPERATURE=1: the variance should change visibly
Exercise 1 — Solution: Project Structure
Files of this solution, in the lab-snippets repository (master branch):
lab-snippets/
├── data/
│   ├── letter-jean-dupont.txt                # inputs (running example)
│   ├── letter-mario-rossi.txt
│   ├── letter-mohammed-ali.txt
│   └── __init__.py                           # helpers to locate data files
├── snippets/
│   ├── lecture_llmaas/
│   │   └── exercise2/
│   │       └── repl_chat_retry.py            # with_retries (reused)
│   ├── lecture_prompting/
│   │   └── example1/
│   │       └── letter_scoring_openai.py      # prompt and schema (reused)
│   └── lecture_governance/
│       └── exercise1/
│           └── compare_models.py             # the solution
└── pyproject.toml                            # dependencies of all snippets
poetry run python -m snippets -l governance -x 1 # default shortlist
poetry run python -m snippets -l governance -x 1 MODEL1 MODEL2@URL ... # custom shortlist
- env vars:
OPENAI_API_KEY(andOPENAI_BASE_URL),REPETITIONS(default5),TEMPERATURE,COMMITTEE_OUTPUT(defaultoutput/)
Responsibility Remains Human
Enveloping: the world adapting to AI
- Machines work well only in environments shaped around them
- a dishwasher does not wash dishes as we do: we build a box where a simple machine can succeed
- industrial robots work in cages, robot lawnmowers need perimeter wires, self-driving cars need mapped and well-marked roads
- Enveloping = adapting the environment (and our own behaviour) so that AI can operate in it (cf. Floridi, 2011)
- digital data, sensors, standard formats, and APIs progressively turn the world into a place where machines can act
- LLMs are agency without intelligence (Floridi, 2023): they succeed because much of our world is already made of text and data
- recall: intelligence, autonomy, and agency are separable dimensions (genai lecture)
Question: when we envelop the world for AI, who decides what changes, and does anyone notice?
Enveloping in the age of LLMs: examples
| What is adapted | How | For which AI |
|---|---|---|
| Websites | llms.txt files, Markdown versions of pages, agent-friendly APIs |
LLM crawlers, coding assistants |
| Web content | generative engine optimisation: content rewritten to be cited in LLM answers (Aggarwal et al., 2024) | AI search engines |
| Software | MCP servers, tool docstrings, structured outputs (cf. agents lecture) | agents |
| Code bases | AGENTS.md / CLAUDE.md files, skills (cf. skills lecture) |
coding assistants |
| Processes | forms, documents, and tickets re-designed to be machine-readable | extraction pipelines |
| People | applicants writing CVs for screening software, authors hiding prompts for AI reviewers in their papers | classifiers, scorers |
- Most of these are reasonable engineering choices…
- … but they change how people write, work, and are evaluated, often without anyone deciding it
Bad vs. good enveloping
Bad enveloping: silent adaptation
- the process shrinks to what the model handles well
- e.g. “typed PDFs in English only”, because extraction fails on the rest
- people learn to please the model, rather than to pursue the goal
- e.g. keyword stuffing, instructions hidden for AI readers
- criteria live implicitly in prompts and weights
- nobody can say what is evaluated, nor contest it
- the adaptation is not decided, documented, or reversible
Good enveloping: explicit, contestable representations
- adapt the world through artefacts humans can read: schemas, checklists, plans, tool contracts, process models
- these artefacts are published, versioned, and can be challenged
- the LLM fills them in, software and humans verify them
- recall: LLMs propose, software verifies (genai), cf. LLM-Modulo
- what the AI does not handle is handled by hand, not dropped
Rule of thumb: if the world must adapt to the AI, make the adaptation visible and contestable: an artefact, not a habit
Enveloping in the running example
Recall the running example (PhD admission committee assistant):
Good: explicit
- the letter checklist makes the evaluation criteria explicit: they can be published in the call for applications
- extraction schemas (Pydantic) state which fields matter, and code validates them
- uncertain fields are flagged for humans, not silently guessed
Bad: silent
- candidates learn which words “the AI likes”, and write letters for the scorer
- or inject instructions into their documents (cf. prompt injection)
- the call restricts the accepted formats to what extraction handles, without saying why
- the committee stops reading letters, and reads scores
The last item is no longer about the world adapting to AI, but about the people using it: see next slides
Responsibility remains human: the general concept
- An AI system cannot be held accountable: it cannot be sanctioned, has no duties, cannot answer for its outputs
- accountability stays with people and organisations: providers, deployers, the humans in the loop
- e.g. in the Italian public administration, the official remains solely responsible (L. 132/2025, Art. 14)
- Yet learning, autonomous systems open a responsibility gap: nobody fully controls, nor can fully predict, their behaviour (Matthias, 2004)
- The usual remedy is a human in the loop… who risks becoming a moral crumple zone (Elish, 2019)
- the human with little actual control absorbs the blame when the system fails, protecting the system itself
- e.g. the safety driver of a self-driving car, the official signing an AI-drafted decision
- Human oversight works only if the human can actually understand, question, and override the output
Responsibility remains human: systems must be designed so that humans can exercise it, not just sign for it
Biases in LLM-agent use
| Bias | What happens | LLM-specific twist |
|---|---|---|
| Over-trust (automation bias, complacency) | humans accept automated outputs without checking them: they miss errors, or follow wrong advice (Parasuraman & Manzey, 2010) | outputs are fluent and look like expert work; checking a long output costs more than accepting it |
| Artificial salience | what the system shows or highlights becomes what humans attend to, the rest is ignored (anchoring) | summaries, scores, and rankings frame the decision before the human reads the sources |
| False certainty | humans read confidence where there is none | LLMs use the same assertive tone whether right or wrong; their verbalised confidence is poorly calibrated (Xiong et al., 2024) |
- Expertise and practice do not eliminate automation bias (Parasuraman & Manzey, 2010)
- Telling users to “be careful” does not fix overreliance, and some mitigations (e.g. explanations) can even increase it (Passi & Vorvoreanu, 2022)
Automation bias in the law
- The EU AI Act names automation bias explicitly: high-risk systems must enable their overseers (Art. 14(4)):
- (a) to understand the system’s capacities and limitations, and to monitor it
- (b) “to remain aware of the possible tendency of automatically relying or over-relying on the output […] (automation bias)”, in particular for systems providing recommendations for decisions taken by people
- (c) to correctly interpret the output
- (d) to decide not to use it, or to disregard, override, or reverse its output
- (e) to interrupt it (a “stop” button)
- Deployers must assign oversight to people with the necessary competence, training, and authority (Art. 26(2)), and support their staff’s AI literacy (Art. 4)
- GDPR (Art. 22): rubber-stamping does not turn an automated decision into a human one
- human involvement must be meaningful, by someone with the authority and competence to change the decision (WP29 guidelines on automated decision-making, endorsed by the EDPB)
Countermeasures: designing for real oversight
| Countermeasure | Against | How, in practice |
|---|---|---|
| Evidence next to outputs | over-trust | show the source (picture, sentence, document) supporting each field or claim: no evidence $\rightarrow$ no claim |
| Surfaced uncertainty | false certainty | flag low-agreement fields (cf. self-consistency), never pre-fill them |
| Independent judgement first | salience | humans judge (at least a sample) before seeing the AI output, then compare |
| Neutral presentation | salience | do not rank, sort, or colour by AI score until humans have reviewed |
| Friction for irreversible actions | over-trust | require an approval with a written motivation (cf. human-in-the-loop tools) |
| Monitoring of overrides | rubber-stamping | too many overrides: the AI is unreliable; too few: humans may have stopped checking |
| Training | all | teach the system’s failure modes (e.g. prompt injection), not just its features |
| Logging and tracing | lack of accountability | who decided what, based on which output, with which model and prompt version |
Oversight is a feature to engineer, with its own requirements and tests, not a checkbox
Human oversight in the running example
Rubber-stamp design
- the assistant extracts fields and scores letters
- the committee sees a ranked list of candidates, with scores
- a member “approves” the ranking
- nobody can tell whether the letters were read
Design for oversight
- fields shown next to the source picture; uncertain fields flagged
- each letter score shown with the sentences supporting each checklist item
- candidates listed alphabetically until reviewed
- a sample of letters scored blindly by a member first; disagreements discussed
- rejections need a written, human motivation
- override rate monitored in both directions
These choices are part of the human oversight decision of Exercise 2
Exercise 2: A Governance Decision Record for the Running Example (pt. 1)
Goal: the University asks the committee to justify the adoption of the admission assistant, before using it on real applications
Deliverable: a document (e.g.
decision-record.md), insnippets/lecture_governance/exercise2/oflab-snippets
TO-DO List
Write a short (2–4 pages) decision record, answering:
- Regulatory classification: is the system high-risk under the EU AI Act? Which obligations follow for the University (as provider and/or deployer? cf. Art. 25)? Which GDPR obligations apply to candidates’ documents?
- Deployment: cloud API, hosted open model, or on-premise? Support the choice with a cost estimate (number of applications per year × tokens per application × price, vs. hardware) and privacy considerations
- Model: which model? Support the choice with the results of Exercise 1, and with the model’s documentation
- apply the pre-adoption checklist to the exact checkpoint: license, multimodal restrictions, derivatives, AI Act role
- Technique: which parts rely on prompting / structured output / tools / RAG? Why not fine-tuning?
- Human oversight: what do humans review, with which countermeasures to automation bias? Who is accountable?
- Monitoring: what is logged, and when is the decision re-assessed (e.g. model deprecation, new regulations)?
Exercise 2: A Governance Decision Record for the Running Example (pt. 2)
Decision points and hints
- Take inspiration from Architecture Decision Records (ADRs, cf. https://adr.github.io/): context, options considered, decision, consequences
- Use the five dimensions (quality, cost, control, compliance, time-to-market) as the evaluation criteria for each option, possibly in a table
- For regulation, cite the article of the law supporting each claim
- For costs, state your assumptions explicitly (e.g. tokens per document), and compute a break-even point
- Be explicit about what the system does not decide: e.g. scores as suggestions to the committee, never automatic rejections
- Be explicit about what the process adapts to the assistant (enveloping): e.g. what candidates are told about how their documents are evaluated
How to assess it?
- Could a colleague reproduce your choice from the record alone?
- Would the record survive a question from the University’s Data Protection Officer?
- Does the record say when it should be revised?
Solution: a walkthrough follows in the next (vertical) column — try on your own first!
Exercise 2: A Governance Decision Record for the Running Example — Solution
⚠️ The walkthrough of a possible solution is about to start
- do not proceed until you have attempted the exercise on your own
- press → to skip it, ↓ to see it
- the sample record is on the
masterbranch oflab-snippets(while you cloned theexercisesbranch):decision-record.md, an ADR-like document (status, context, sections 1–6, consequences) - below, a summary of its key sections: read the full record for the details (and the article of the law behind each claim)
Exercise 2 — Solution: Regulatory Classification
Decision 1: the system is high-risk, and the University is both its provider and its deployer
EU AI Act
- high-risk: “access or admission” to education (Art. 6(2), Annex III 3(a)); the “preparatory task” derogation (Art. 6(3)) is not claimed: scoring materially influences the outcome; and anyway, scoring candidates is profiling, which Art. 6(3) (last subparagraph) makes always high-risk
- University = provider (it builds the system on a general-purpose model): risk management, logging, oversight by design, conformity assessment, registration (Art. 9–17, 43, 49)
- University = deployer (and public body): trained oversight, logs ≥ 6 months, FRIA (Art. 26–27); candidates’ right to explanation (Art. 86)
- applies from 2 Dec 2027, but we comply from the first use
GDPR, Italian law, UniBo policy
- lawful basis: public interest task (Art. 6(1)(e))
- special categories may appear incidentally (e.g. courses revealing religion): never used for scoring (Art. 9)
- no solely automated decisions (Art. 22): scores are suggestions
- DPIA required (Art. 35), mergeable with the FRIA; external providers are processors under a DPA (Art. 28)
- L. 132/2025 (Art. 14): in the public administration AI is only instrumental, the official stays responsible
Exercise 2 — Solution: Deployment Options and Decision
Decision 2: the five dimensions as criteria; 500 applications/year ≈ 17.5M input + 2.5M output tokens/year
| Option | Quality | Cost per year | Control | Compliance | Time-to-market |
|---|---|---|---|---|---|
| A. proprietary API (e.g. Claude Haiku 4.5) | high | ≈ \$30 | low: snapshots can be pinned, but are retired by the vendor | DPA + transfer safeguards; data leaves the University | days |
| B. open-weights model, hosted by an EU provider (e.g. Mistral La Plateforme, Scaleway, OVHcloud) | medium-high | ≈ \$1–10 (cf. the worked example) | medium: pinned checkpoint | DPA; data stays in the EU | days |
| C. open-weights model, on-premise (24 GB GPU) | medium | ≈ €2.5k upfront + energy + maintenance | full | data never leaves the University | weeks |
- break-even of C vs. B: centuries (even vs. A: ≈ 80 years) → at this scale, cost is not the deciding factor: compliance and control are
- Decision: B for the pilot, with the same model runnable on-premise (C) should the DPO object; A discarded: pinned snapshots (cf.
gpt-4o-2024-08-06in LLM-as-a-Service) are retired on the vendor’s schedule, forcing re-validation; and data would leave the University - Decision 3 (model): a decision rule applied to Exercise 1’s table (no failures, lowest error, sd ≤ 0.5, then latency and cost), whose cells are left as [Ex. 1] placeholders, to be filled from your run
Exercise 2 — Solution: Human Oversight
Decision 5: what is reviewed by whom, who is accountable, and how automation bias is countered
Review and accountability
- every extracted field is shown next to the source picture; flagged fields are confirmed by the secretary
- every letter score is shown with its checklist; overrides are logged with a reason
- committee members decide, under their name; the chair is accountable for the final ranking, and answers requests for explanation
- members are trained on the assistant’s limitations (e.g. prompt injection in documents; scores are not grades)
- enveloping, explicitly: checklist and schemas are published in the call; formats the assistant cannot handle are processed by hand
Countermeasures against automation bias (Art. 14(4)(b))
- independent judgement first: 20% of letters are scored by a member before seeing the assistant’s score
- evidence, not verdicts: each satisfied criterion comes with the supporting sentence of the letter
- no false certainty: uncertain fields are never pre-filled; candidates are listed alphabetically, not by score, until all are reviewed
- friction: a rejection needs a written motivation by a member, not copied from the assistant
Exercise 2 — Solution: Monitoring
Decision 6: what is logged, and when the decision is re-assessed
- logged: model and checkpoint, prompts’ version, tool calls, extractions, scores, human overrides
- override rate monitored in both directions: too many overrides $\rightarrow$ unreliable assistant; too few (or no disagreement in the blind sample) $\rightarrow$ rubber-stamping
- test suites re-run before each admission round, and at every change of prompt, model, or provider
- re-assess when: the model is deprecated or changed, tests fail, overrides exceed 20% or fall below 2% in a round, regulations or guidelines change, the DPO asks, or by the revise-by date
Consequence: the committee’s workload moves from reading to reviewing, and reviews must be real, not rubber stamps
Exercise 2 — Solution: Project Structure
Files of this solution, in the lab-snippets repository (master branch):
lab-snippets/
└── snippets/
    └── lecture_governance/
        ├── exercise1/
        │   └── compare_models.py   # produces the results table (Exercise 1)
        └── exercise2/
└── decision-record.md # the decision record (this solution)- nothing to run: the deliverable is a document
- to fill in its [Ex. 1] placeholders, run
poetry run python -m snippets -l governance -x 1, and paste the printed table
Check your understanding
-
Answer in your own words, motivating your conclusions and using examples where useful.
-
Questions asking whether something is possible or desirable require more than a yes/no answer.
-
Implementation questions can be answered with an explanation or pseudocode unless executable code is explicitly requested.
-
Labels identify the primary learning target:
- notions (knowledge), reasoning (drawing conclusions), or know-how (applying knowledge).
- theoretical questions are independent of particular technologies; practical questions concern their use.
-
Practical answers should identify the technology used, without requiring memorisation of product-specific details (model names, prices, API signatures, versions, limits).
Check your understanding (1/5)
Making and documenting choices
-
[notions, theoretical] What is AI governance in an organisation, and which decisions belong to it? Explain why choosing an architecture or model can be a governance decision even before a legal question arises.
-
[reasoning, theoretical] How would you compare two plausible designs when one offers better quality and faster delivery, while the other offers more control and easier compliance? Explain how quality, cost, control, compliance, and time-to-market can conflict, and what evidence would justify your choice.
-
[know-how, practical] A university wants to process applicants’ documents with an LLM. How would you compare a proprietary API, a third-party host of an open model, and an on-premise deployment? Identify who handles the data and operations in each case, and when a hybrid arrangement would help.
-
[reasoning, practical] How would you estimate whether paying per request or running your own model is cheaper for a particular workload? State the assumptions you would need, including volume, token use, hardware utilisation, labour, and maintenance, and explain why the cheapest option may still be unsuitable.
Check your understanding (2/5)
Rules and responsibilities
-
[notions, practical] Which different questions are answered by data-protection law, AI-specific regulation, national law, institutional policy, provider contracts, and model licenses? Explain why satisfying one layer does not settle the others.
-
[know-how, practical] Before sending identifiable application documents to an external LLM provider, what would you investigate and document? Discuss purpose and minimisation, the controller–processor relationship, retention and logs, international transfers, impact assessment, and the possibility of significant automated decisions.
-
[reasoning, practical] Why can the same model be used in one minimal-risk application and in another application subject to high-risk obligations? Apply this distinction to a system that scores applicants, and explain what changes if its output merely informs a committee rather than automatically rejecting people.
-
[know-how, practical] An organisation builds an admission assistant on top of a third-party general-purpose model. How would you identify the model provider, the system provider, the deployer, and affected people? What kinds of duties would you examine for each role, including human oversight, documentation, monitoring, and transparency?
-
[reasoning, practical] An AI system seems permissible under a general EU rule, but a national rule or the organisation’s policy imposes tighter conditions. How should engineers handle this during design and procurement, and who should help resolve uncertain interpretations?
Check your understanding (3/5)
Openness, licensing, and sovereignty
-
[notions, theoretical] In what different senses can an AI model be called “open”? Explain what weights, code, training recipe, data or data information, documentation, and licenses each let a user inspect or do, and why downloadable weights alone do not establish reproducibility.
-
[reasoning, practical] A model is advertised as “open source.” How would you examine that claim for both practical reuse and auditability? Explain why a normative definition of open-source AI and a regulatory exemption for open general-purpose models may set different thresholds.
-
[know-how, practical] A team plans to fine-tune, merge, or distil an open-weights model and sell access to the result. What exactly would you check before proceeding? Include the checkpoint and license version, upstream models, training data, outputs, downstream distribution, and the team’s possible regulatory role.
-
[reasoning, theoretical] What might an organisation mean by “sovereign AI”? Distinguish where a model was developed, where it runs, and how much of its construction can be audited. How would you assess a local-language or nationally developed model without assuming its origin makes it better, more open, or more suitable for production?
Check your understanding (4/5)
Choosing techniques and models
-
[know-how, theoretical] A system fails because it lacks current facts, must perform actions, follows a repeatable procedure, and sometimes produces the wrong style. Which of prompting, RAG, tools or agents, skills, workflows, and fine-tuning might address each problem? Explain how you would add complexity only where evidence warrants it.
-
[know-how, practical] How would you form a shortlist of models for a real application? Separate hard constraints from qualities you would rank, and explain what model cards, system cards, dataset documentation, provider terms, and your own tests can and cannot establish.
-
[reasoning, theoretical] Why might a model that leads a public benchmark or leaderboard perform poorly in your application? Discuss benchmark saturation, contamination, changing test conditions, task mismatch, and the difference between a reported capability and a dependable workflow outcome.
-
[know-how, practical] How would you compare several models for scoring applicants’ letters? Design a small evaluation that considers a human reference, repeated runs, disagreement, invalid outputs, latency, and cost, and explain how you would choose a model and know when to revisit the choice.
Check your understanding (5/5)
Human responsibility and oversight
-
[reasoning, theoretical] What does it mean to adapt a process or its users to an AI system? Contrast an explicit, contestable change to an admission procedure with a silent change that favours what the model handles well. Who should be able to notice and challenge such adaptations?
-
[reasoning, theoretical] Why can placing a human “in the loop” fail to provide meaningful oversight? Explain the responsibility gap, automation bias, artificial salience, and false certainty, and how a nominal approver can end up bearing blame without real control.
-
[know-how, practical] Design the committee’s review of AI-extracted facts and suggested scores so that members can exercise independent judgement. Explain what evidence they see, when they see the AI’s ranking, how uncertainty and overrides are handled, and how you would detect rubber-stamping over time.
-
[know-how, practical] What would you put in a governance decision record before deploying an admission assistant? Explain how a colleague could reconstruct the regulatory classification, alternatives, deployment and model choice, evaluation evidence, human responsibilities, monitoring plan, and conditions that trigger reconsideration.
Lecture is Over
Compiled on: 2026-10-22 — printable version